How to Think in the AI Era: Crash Course
6 Disciplines · 6 AI Failure Modes · One Rule
Two people open the same AI tool on Monday morning. They have the same task. Should they spend their budget on one experienced hire, or on AI tools that help everyone on the team work faster? Both have Claude, ChatGPT, and Gemini. Both have one week to decide.
Person A finishes Friday with a clear recommendation she can explain. She wrote down which AI claims she agreed with, which ones she pushed back on, and what would make her change her mind. Person B finishes with a polished document that repeats what AI told her on Monday. When her boss asks "why did you recommend this?" she cannot explain her own reasoning.
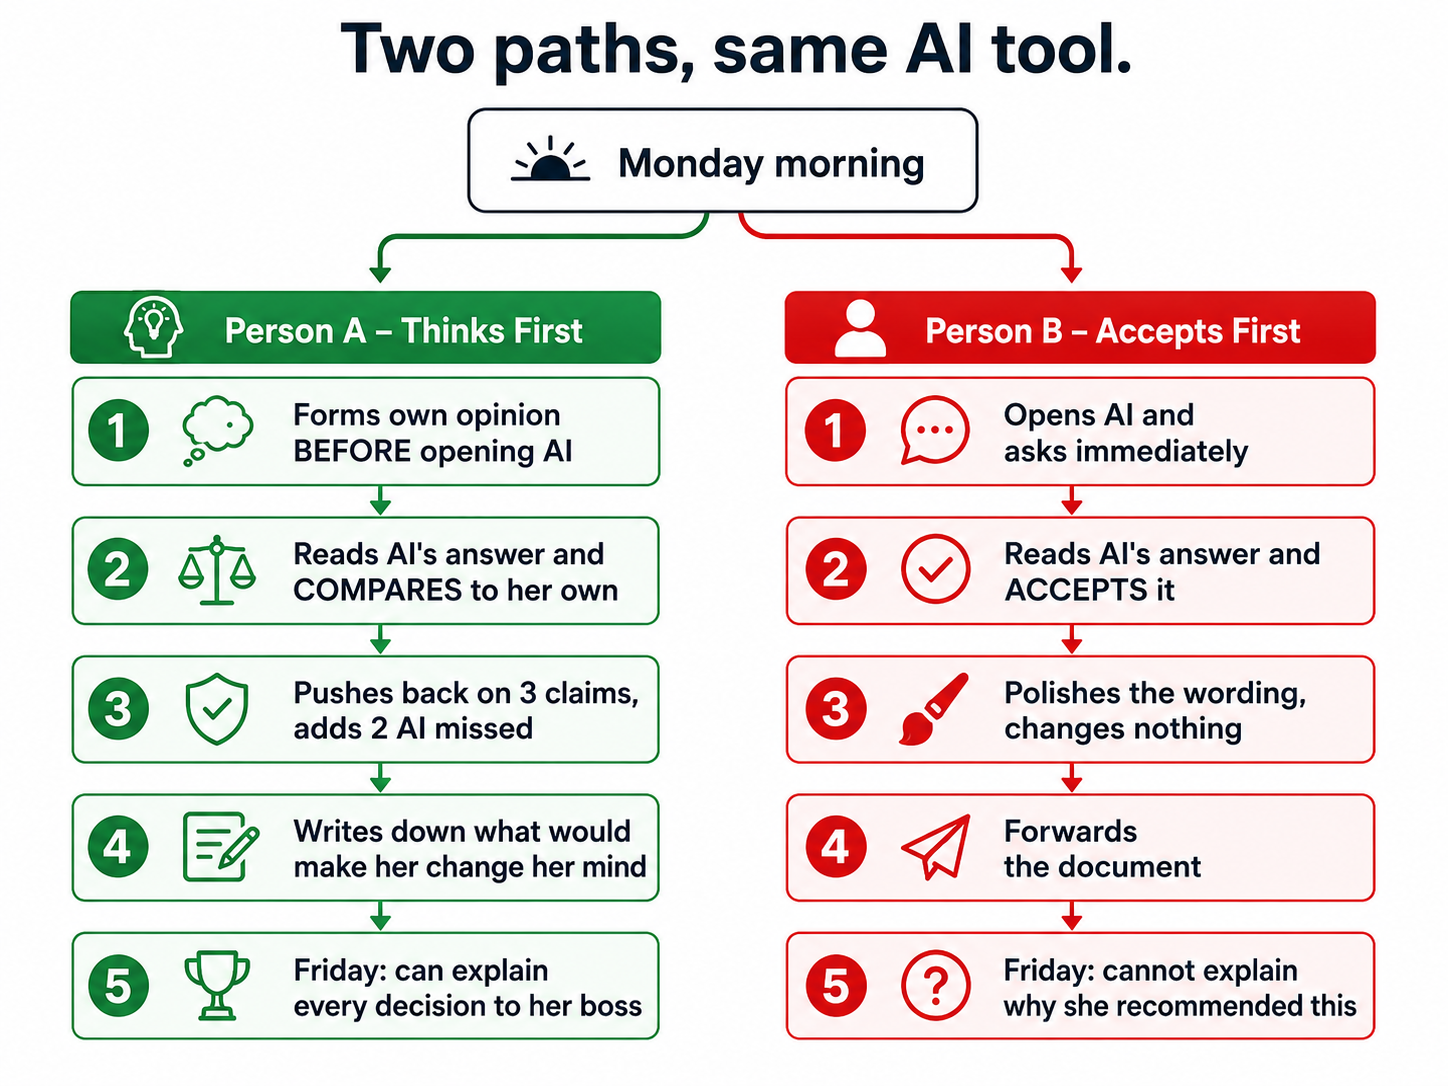
Person A formed her own opinion before asking AI. Person B let AI's first answer become her opinion.
That gap is what this crash course closes. Six thinking habits, three short parts, no code. Each habit answers one way AI misleads you. Without them, AI is an answer machine. You ask, it answers, you accept. With them, AI is a thinking partner. You predict first, it answers, you compare, you decide.
The force this course trains against
Person B is not lazy. She is not careless. She is being pulled by a force that now has a name.
Eric So, a professor at MIT Sloan, calls it AI gravity, which he describes as "the constant pull and push to outsource more of our thinking to AI." (MIT Sloan, June 2026) In plain words: every day it gets a little easier to let AI do your thinking, and a little easier to stop doing your own.
Why call it gravity? Because it works like real gravity. You cannot see it. It never turns off. It pulls on everyone, all the time, from three directions at once.
- Your brain wants to save energy. Brains are built to avoid hard work. That is normal, not a flaw. But every time AI gets smarter, handing it one more task feels easier, and writing your own answer first feels like extra work you can skip.
- You want your work to look expert-level. AI can write something in seconds that looks like an expert made it. Working without it starts to feel like racing with one shoe.
- You cannot see who else is using AI. Your classmates and coworkers do not announce it. So everyone assumes everyone else is using AI more, and nobody wants to fall behind. The race speeds up on its own.
Now look back at Person B on Monday morning. All three forces pushed her toward the same easy move: open AI, ask, accept. She never felt herself decide anything. That is what a gravity well feels like from the inside.
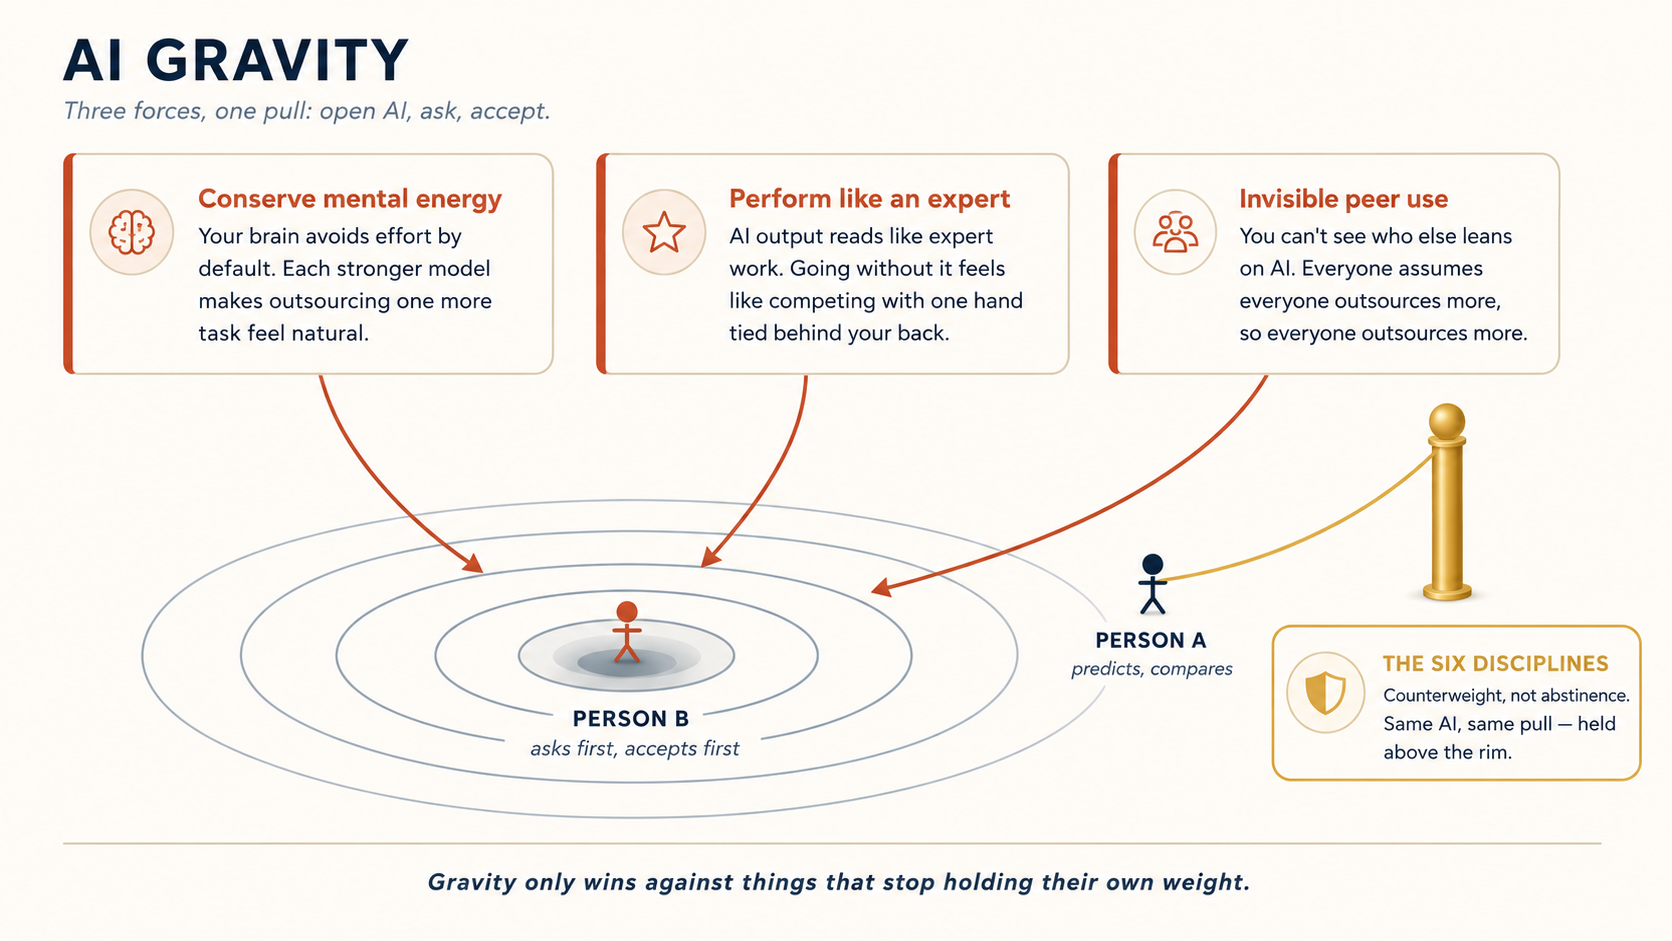 Three forces, one pull. Person A faces the same gravity as Person B. The difference is the counterweight.
What the pull costs you. Researchers at the MIT Media Lab ran an early study on exactly this. People wrote essays with ChatGPT's help. Right after handing them in, 83 out of every 100 could not repeat one sentence from their own essay. The words went from the screen to the homework without passing through the writer's head. The study is preliminary, meaning early and small, but the warning is hard to miss.
Professor So has a name for what gets lost: cognitive capital. It is your built-up ability to work through a problem, spot a wrong answer, and notice what a confident answer left out. Think of it as a muscle, not as money in a bank. Money sits still while you ignore it. This ability fades when you stop using it. Every discipline on this page runs on that muscle. The Prediction Lock only works if you can form your own position. The Error Taxonomy only works if you know what a real number looks like. Lose the muscle and the disciplines have nothing to work with. Skills do not collapse in one day. They collapse one accepted answer at a time.
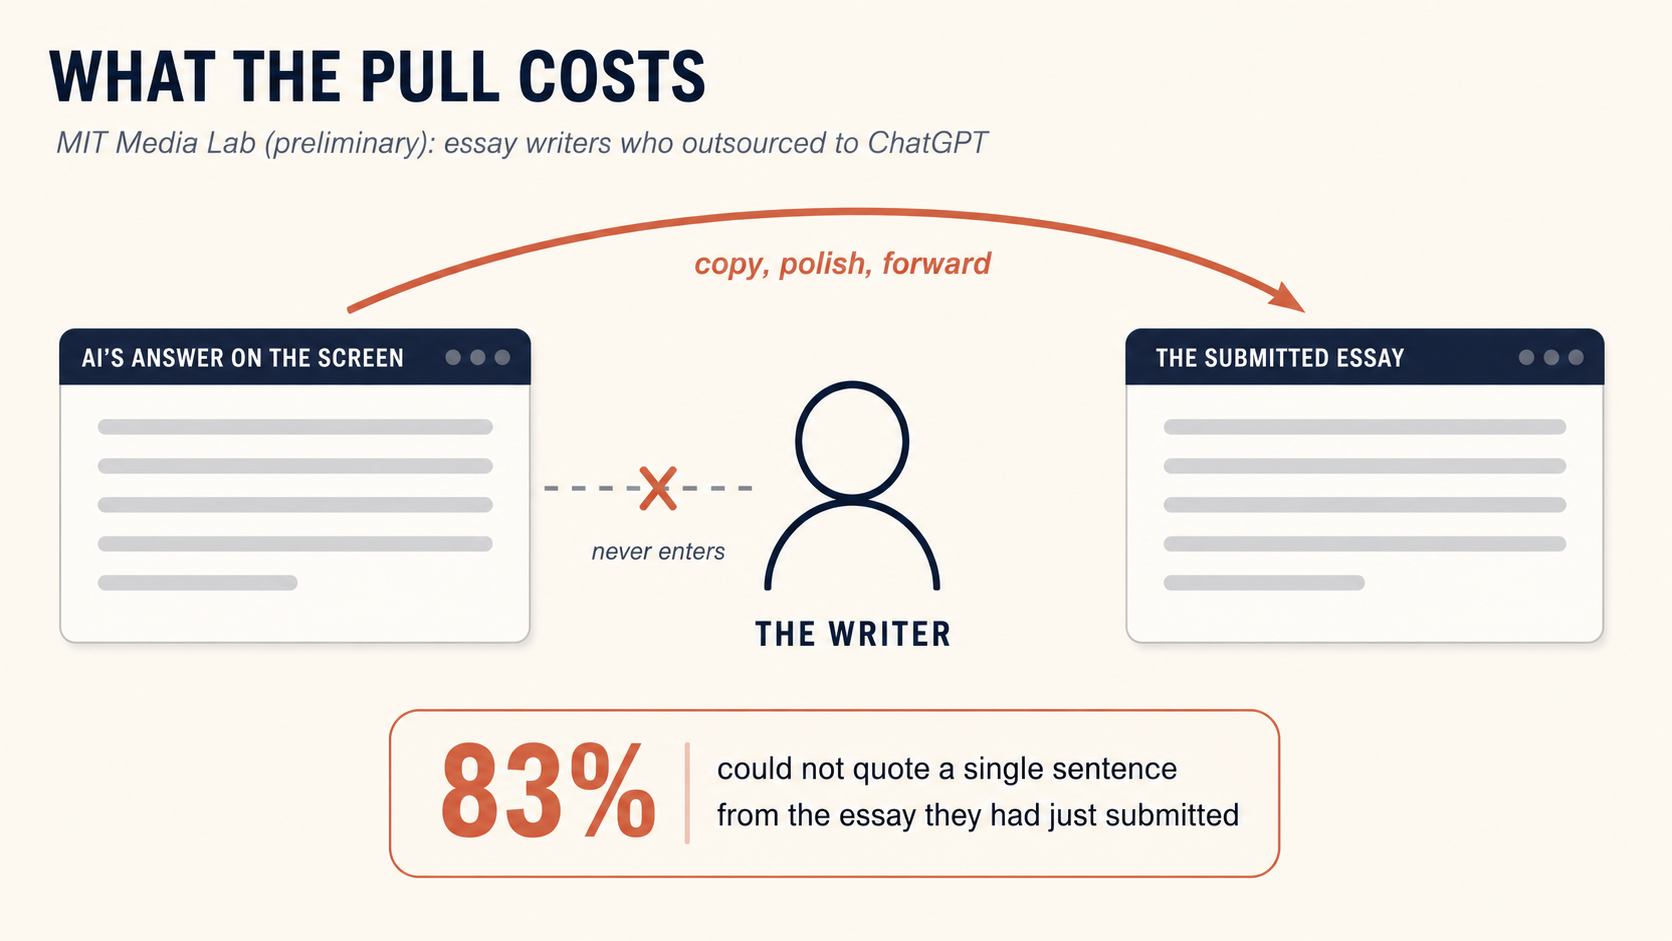 The words traveled from the screen to the submission without ever passing through the writer.
Teachers feel the same pull. In June 2026, a dean at IE School of Science & Technology in Madrid said the real danger of AI in school is not a worse summary. It is that students stop building the mental muscle that writing summaries was meant to build. Her advice was simple. Keep doing the hard thinking, and add AI on top. (BusinessWorld, June 2026)
Professor So also gives four ways to push back against the pull. You will recognize all four, because they are what this page teaches.
| How to push back (from Professor So) | Where you will practice it on this page |
|---|---|
| Keep doing the hard thinking yourself | The exercises, and the caution box below: use AI to stretch a skill, not to skip it |
| Know what you can do without AI | The Prediction Lock (your answer before AI's) and the Solo path in Discipline 6 |
| Spend the time AI saves you on harder thinking | Part 3, Origination: the thinking AI cannot do for you |
| Use AI as a coach, not an answer machine | Every graded exercise on this page. AI grades your thinking instead of replacing it |
One thing this section is not saying: use AI less. The six disciplines are not a diet. They are the counterweight. You keep using AI, and you keep doing the thinking that decides what to do with its answer. The rest of this page teaches that thinking, one habit at a time.
Prerequisites. This page assumes you have finished the earlier Foundations courses, especially What AI Actually Is for the mental model and AI Prompting in 2026 for the mechanics. This course teaches the thinking discipline that makes those mechanics pay off. Open a free account with Claude, ChatGPT, or Gemini in another tab now. You will use it in the practice sections.
A note on AI models. The practice exercises include AI-graded feedback. They work best with a strong, current model, such as Claude, ChatGPT, or Gemini at their best reasoning level. Weaker models give vague or overly positive feedback whatever you submit. The brand does not matter. What matters is that the model can reason carefully.
📚 Teaching Aid
View Full Presentation, Thinking with AI
The rule in one line
The deliverable is never the answer. The deliverable is the documented evidence of thinking.
Read that as two claims. First, the deliverable is the thing you hand to your boss, your professor, or your client. It is no longer just the answer. AI can produce a polished answer in seconds, so producing one is no longer the hard part. Second, what makes a deliverable trustworthy now is the written record of how you thought. That record holds the prediction you locked in before asking AI, the row where you marked one of AI's claims as REJECT and said why, and the cascade map you drew to trace the side effects. Discipline 4 explains the cascade map in full. If someone asks "why did you decide this?", you point at the evidence.
In practice, the evidence usually lives inside the deliverable, as a footnote, a "considered and rejected" paragraph, a cascade map as a figure, or a "what would change my mind" sentence near the end. Sometimes it lives in a working doc beside it. Either way, when someone asks why, you can point to it. If you cannot point at anything, you have an answer you cannot defend.
Sometimes. A chat session captures everything AI said and everything you asked, which is more complete than any reasoning receipt. For low-stakes work, such as debugging code or quick research, the chat link by itself is often enough. For serious deliverables it has three limits. It shows what AI said but not what you decided about each claim. It is too long for a busy reader to scan. And it does not show what AI got wrong, because the catches live in your head, not in the transcript. Treat the chat link as raw material, the way an academic paper treats raw data. The receipt or memo is what you hand to the audience. The chat link goes in the appendix for anyone who wants to verify.
Friday morning, the boss asks Person A and Person B the same question. Why did you recommend this? Person B has nothing to point to. She forwards the document and says it sounded right. The boss finds two claims he disagrees with, and cannot tell whether she examined them or just accepted them. Person A opens her working doc and answers: "I predicted on Monday that the experienced hire would be better. AI's analysis flipped that prediction. Here are the three claims I checked, the one I rejected, and the assumption that would change my recommendation back." Same problem. Two completely different conversations.
What does the evidence buy you? Two things. One: the act of writing forces the thinking to happen. You cannot write a specific prediction without first deciding what you believe, and you cannot mark a claim as REJECT without explaining why. Without the writing, the thinking is easy to skip. You read AI's polished answer, it sounds right, and you adopt it without ever forming a position to compare it against. Two: the record is a working tool, not just a trail for someone else. The bank manager wrote "my recommendation is to close the branches, because I think most of these customers are app-only." AI came back with data showing only 45% were. That gap became the opening line of her report. The record is where the second pass of thinking happens, and the second pass is where the deliverable improves.
What changed is not the habit of writing things down. It is the cost of skipping it. When polished output was expensive, the hard part was making the thing. AI made polished output free. The bottleneck moved from producing work to evaluating it, and the written evidence is how you do the evaluation. Tools change every six months. This does not.
The essentials (five bullets)
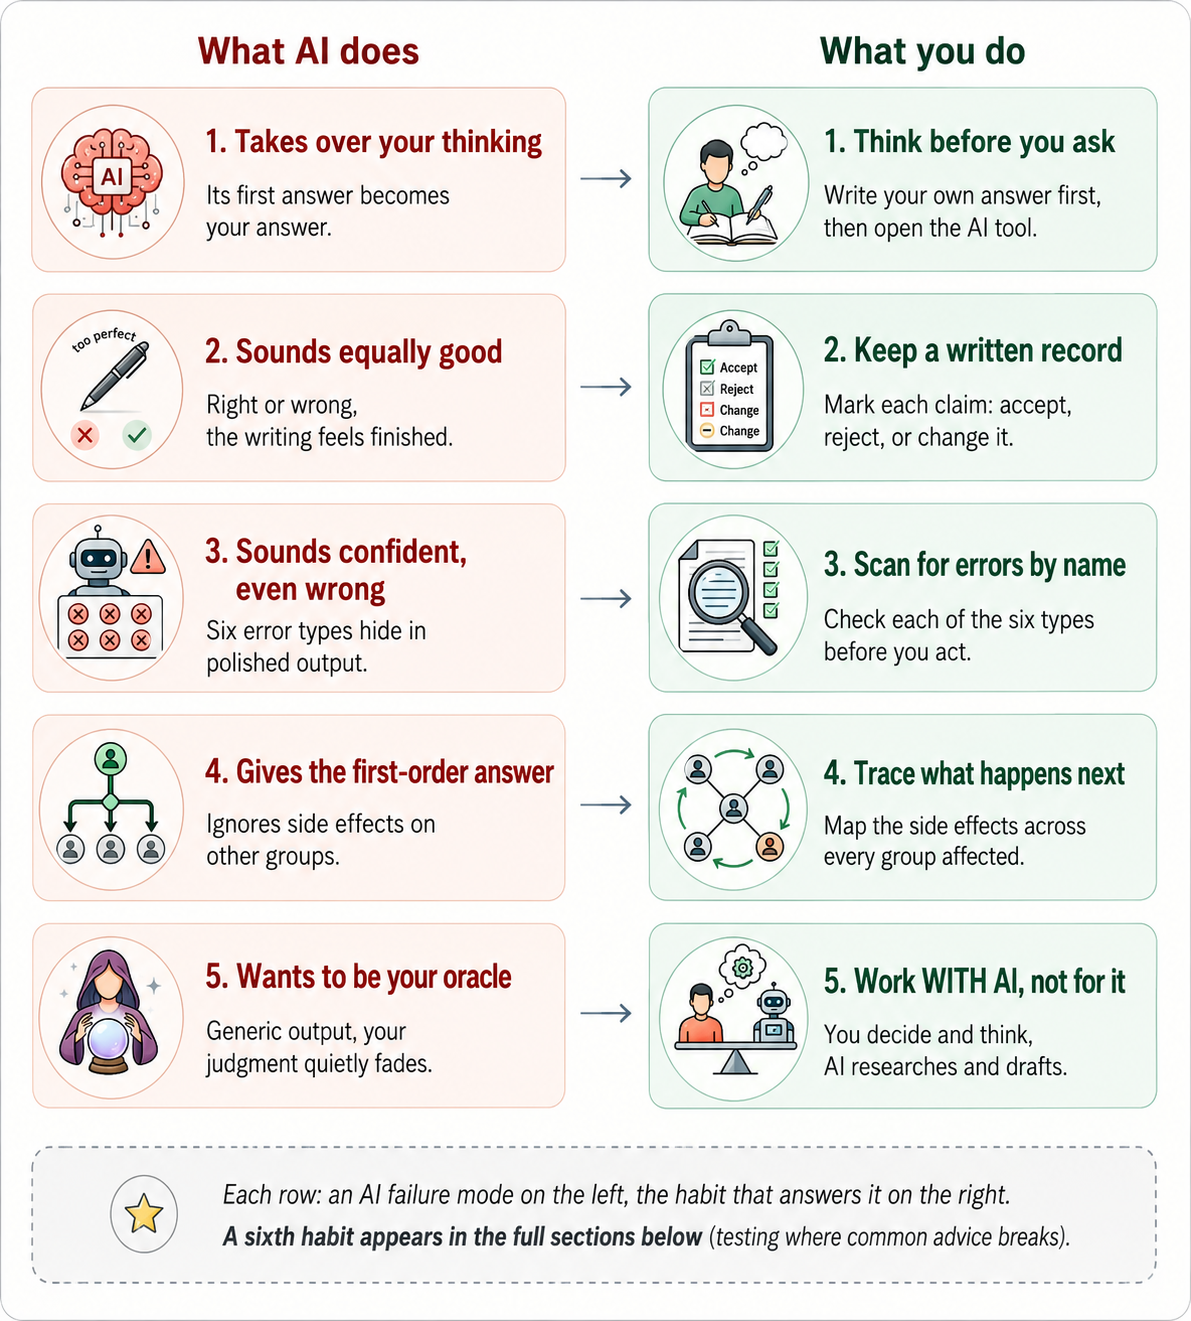
Here are five of the six habits in short form. The sections below show you how to run each one. The sixth habit, testing where common advice breaks down, needs more setup than a bullet can give.
-
Think before you ask AI. Write down what YOU think the answer is before you open any AI tool. Once you read AI's answer, it takes over your thinking. Writing your own answer first protects your independent judgment.
-
Keep a written record of what you accepted and what you rejected. Go through AI's claims one at a time. Do I agree? Do I disagree? Did AI miss something important? Write one sentence of why for each. If you agree with everything, you did not think hard enough.
-
Polished writing is not the same as correct writing. AI sounds confident and professional even when it is wrong. Six specific types of error hide inside smooth AI output. Check for each type by name before you send, publish, or act on anything AI wrote.
-
The obvious answer is never the complete answer. AI answers the thing you asked about and ignores the side effects. Before any important decision, trace what happens next across the groups affected. Look for places where the side effects circle back and undo the decision.
-
The best results come from working WITH AI, not handing it the wheel. Working alone is slow. Letting AI do everything produces generic output. You do the thinking and deciding while AI does the research and drafting. Flip that, so AI thinks and you only edit, and you become unnecessary.
The full framework: six disciplines
The five bullets above are the working summary. Here is the full architecture: six disciplines, paired one-to-one with the AI failure modes they answer, grouped into three parts.
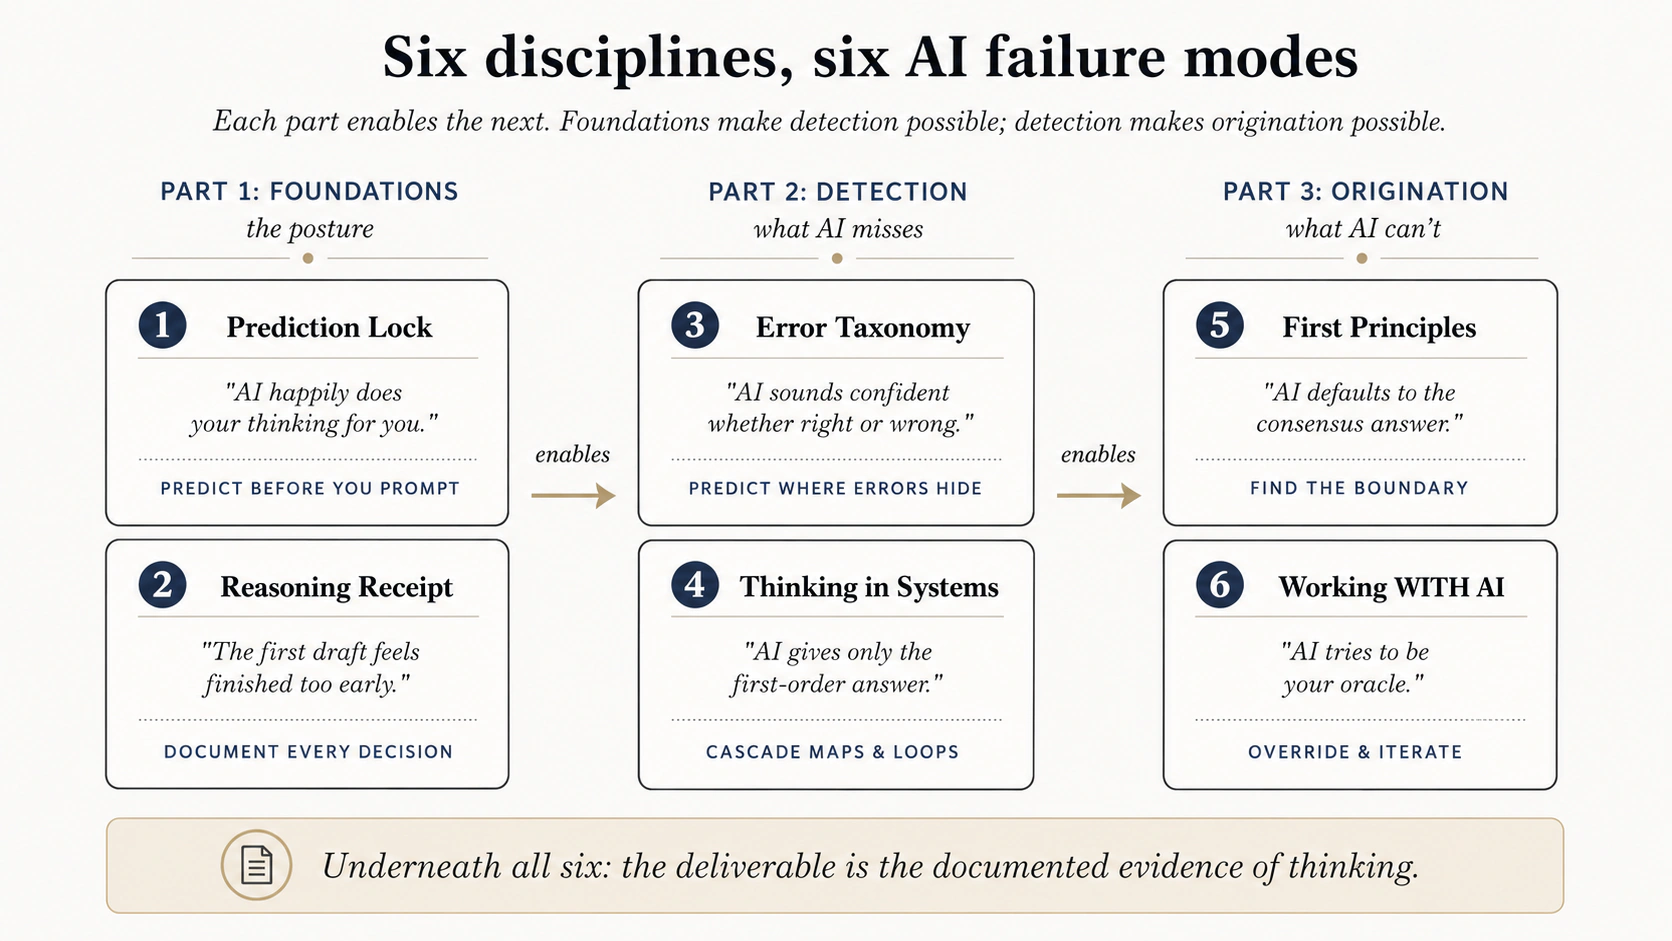 Figure 1: Six disciplines map to six AI failure modes, arranged in three parts.
Four terms recur on this page. A discipline is a thinking habit you practice, so it is something you do. A failure mode is a specific way AI misleads you, so it is something AI does. Each discipline is paired one to one with the failure mode it answers, shown as the italic line under each name in the figure. A part is a group of disciplines that share a job. There are three parts, Foundations, Detection, and Origination, two disciplines each, and each part enables the next. A deliverable is what you hand to your boss, professor, or client. In 2026 that is the answer plus the documented evidence of thinking that produced it.
Each numbered box in the figure is one discipline. The small caps line at the bottom is the action line, the one action that discipline asks you to take, short enough for a sticky note. The name tells you what the habit is called. The action line tells you what to do.
The six disciplines in one line each.
- Prediction Lock. Write your own position, and what would flip it, before you open AI.
- Reasoning Receipt. Give every AI claim a one-word label and a one-sentence reason.
- Error Taxonomy. Hunt AI's output for six named types of mistake, one type at a time.
- Thinking in Systems. Trace what your decision causes next, across every group it touches.
- First Principles. Find the exact condition where the advice everyone repeats stops working.
- Working WITH AI. Do one task three ways, and keep the places where your judgment won.
Quick glossary
Twenty words, one line each. Skip this block and come back when a word stops you.
- AI gravity: the constant pull to hand more of your thinking to AI.
- cognitive capital: your thinking muscle, built up by doing hard thinking yourself.
- discipline: a thinking habit you practice. Something you do.
- failure mode: a specific way AI misleads you. Something AI does.
- part: a group of disciplines that share a job. This course has three parts.
- deliverable: what you hand to your boss, professor, or client.
- documented evidence of thinking: the written record of how you reached the answer.
- action line: the one action a discipline asks you to take, short enough for a sticky note.
- Prediction Lock: your own written position, committed before AI answers.
- Reasoning Receipt: one row per AI claim, saying what you did with it and why. The labels are ACCEPT, REJECT, MODIFY, SURFACED, and MISSED.
- Error Taxonomy: six named types of AI mistake, checked one type at a time.
- Thinking in Systems: refusing to stop at the first effect of a decision.
- Cascade Map: the one-page drawing of what a decision causes, three layers deep.
- loop: a chain where a later effect circles back and changes the original decision.
- First Principles: testing common advice against your own case instead of accepting it.
- named threshold: the exact number or condition where a piece of advice stops working.
- Working WITH AI: you do the thinking and deciding, AI does the research and drafting.
- three-path comparison: doing one task three ways, Solo, AI-only, and Collaborative, then comparing them.
- premortem: imagining that your plan already failed, then listing the reasons why.
- Decision Dossier: one private file holding the whole trail of one real decision.
How to read this page
| Time you have | What to read | What to skip |
|---|---|---|
| 45 minutes | Habits 1, 2, 3, and 6 (read only, no exercises) | Habits 4 and 5 (come back later) |
| 90 minutes | All six habits + worked examples, read-only | The graded exercises |
| A working day (recommended) | Everything, run each exercise on a real decision from your week | Nothing |
These habits stick when you try them on real problems from your week. Reading shows you the moves. Doing the exercises on real decisions is how they become yours.
Every habit here needs something to work with. The Prediction Lock asks you to write your own answer first, and you can only do that if you know enough to have one. The Error Taxonomy asks you to spot a fake number, and you can only spot it if you know what a real one looks like. These habits use your judgment. They do not build it.
So if you are still a student, do not skip the hard work. Write the summary yourself. Solve the problem set without AI. Yes, AI can do it faster. But doing it yourself is how your brain gets strong enough to catch AI when it is wrong later. This is Professor So's first rule for beating AI gravity: keep the struggle. Remove the wrestling and you remove the skill, and you only find out later. If you never do the hard work, your Prediction Lock is just a guess. AI gives an answer, and you have nothing of your own to compare it to.
Simple rule: use AI to stretch a skill you already have, not to skip learning it. An accountant with twenty years of experience can rely on AI a lot, because they know what a good answer looks like. A first-year student who has never done the work by hand cannot, not yet.
Part 1: Foundations (the posture, meaning the stance you take before you start)
If you skip everything else, do not skip these two habits. They fix the two biggest mistakes people make with AI.
-
Mistake 1: AI thinks for you. You ask a question, AI gives a smooth answer, and you accept it before you have formed your own opinion. Habit 1, the Prediction Lock, fixes this. You write down what you think BEFORE opening AI.
-
Mistake 2: AI's first draft looks finished. The writing is so polished that you send it without checking whether it is actually correct. Habit 2, the Reasoning Receipt, fixes this. You go through each claim and write down whether you agree, disagree, or need to verify.
Together, these two habits keep the thinking with you and the typing with AI. Everything in Parts 2 and 3 builds on them.
Discipline 1: The Prediction Lock
The Prediction Lock is a written position of your own, committed before AI's answer arrives. That is the whole goal. Everything below, the four lines and the confidence percentage, exists to make that one thing happen. If you write all four lines and still cannot say what your position was before you opened AI, the discipline did not work. The four lines are only the method. The committed position is the result.
Here is what usually happens without the lock. You ask AI an important question. AI gives a confident, well-written answer. You think "that sounds right" and go with it. Two days later someone asks "why did you decide that?" and you realize it was AI's answer, not yours.
The fix takes three minutes. Write four lines on a piece of paper before you open AI. Let's try it together on someone else's decision first.
Maya is 13. Her school emailed: pick one summer activity. Option 1 is debate camp, two weeks, and all her friends are going. Option 2 is a coding bootcamp, one week, and she is curious but nervous. Her dad says "just ask ChatGPT, it'll know."
Before Maya asks AI, she writes four lines:
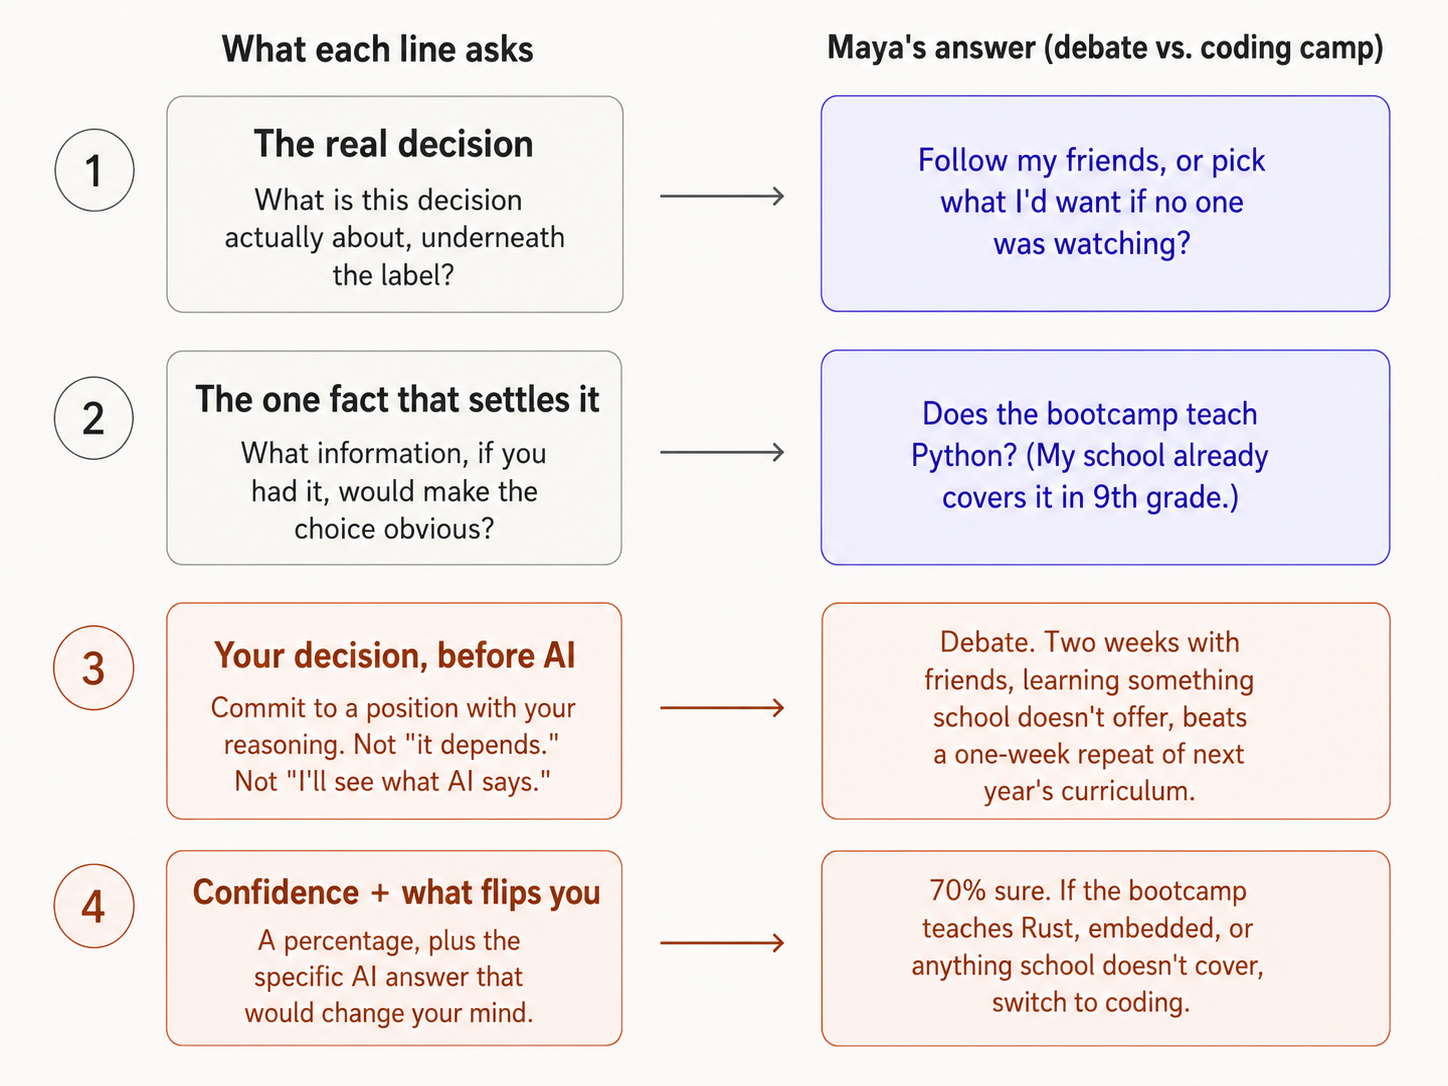 Figure: the four lines of the Prediction Lock, with Maya's answers as a worked example.
Line 1: What is this decision really about?
Not "debate or coding." That is just the surface. The real question underneath might be "am I going to do what my friends do, or what I would pick if nobody was watching?" Or "would I regret missing coding more than missing debate?" Write the real question in one sentence.
Line 2: What is the ONE fact that would help the most?
Not "which is better?" That is too vague. Ask something specific you can check, such as "does the coding bootcamp teach Python?" Her school already teaches Python in 9th grade. If the bootcamp teaches the same thing, the week mostly repeats what she will learn anyway. If it teaches something her school does not cover, it offers a skill she could not get elsewhere.
Line 3: What is your decision, before AI weighs in?
Take a position. Not "it depends." Not "I'll see what AI says." Pick debate or coding, and write down why. Maya's reasoning: her school covers Python in 9th grade, the bootcamp most likely covers Python too, and two weeks with friends learning something the school does not offer beats a repeat of next year's curriculum. Her decision is debate.
"How can I decide without asking AI first?" You can. You already know what your school teaches, what you would regret missing, and what your friends are doing. Use that to form a position. AI's job is to confirm or overturn it, not to form it for you.
Line 4: How confident are you, and what specific AI answer would flip your decision?
Pick a percentage: 60%, 75%, anything. The exact number does not matter. What matters is that you committed. Then write the one AI answer that would change your mind. Maya wrote: "70% sure debate is the right call. If the bootcamp teaches something my school doesn't, such as Rust or game development, coding wins."
If you cannot name the specific AI answer that would flip your decision, you have not committed to a real position yet. "It depends" is not a position. "I'll do X unless AI tells me Y" is a position.
How do you know the lock worked?
There is one test, and it does not involve counting lines.
Can you say, out loud, what your position was before you opened AI, and what would have made you change your mind?
If yes, the lock worked. If you find yourself saying "well, AI said X so I went with X", it did not. The line count does not matter either way.
The four lines are a starter format. After a few weeks you may compress all four into a single paragraph, and the lock will still work. But write them out for the first ten times. It is the only way to know you committed to a position rather than only thinking you did.
What the four lines are doing
The four lines work for Maya because her decision is simple. One choice between two options, one fact that would settle it. Not every decision looks like that. Underneath the template, the Prediction Lock has four parts, and they are the same four parts for any decision.
- Surface the real decision. Strip away the label. Maya's surface decision was "debate or coding." Her real decision was "follow my friends or pick on my own." The label always hides the actual question. Name the actual question.
- Identify what would settle it. What information, if you had it, would make the decision obvious? For Maya, one fact. For a hiring decision, three facts. For a budget split, one comparison. Name them specifically enough that you could verify each one. The number depends on the decision. The requirement that they be checkable does not.
- Commit to a position. Based on what you already know, before you check anything with AI, what would you do? Write it down with the reasoning that supports it. A position is a what plus a why, not just a what.
- Name the reversal condition. What specific finding would change the position? For a hire: if the second candidate's reference comes back much stronger than the top candidate's, switch. If you cannot name what would flip you, you have not committed. You have a preference.
Maya's sticky note fits on four lines because her decision is small. A bigger decision, such as a hiring round, might take a paragraph per part and fill a page.
A worked example with a different shape. You are hiring one of three software engineers and have a week to decide.
- Real decision: not "who is best on paper" but "which of these three would still be productive in twelve months, when the codebase has changed twice."
- What would settle it: three things, not one. Each candidate's track record on long projects, their willingness to learn unfamiliar tools, and a reference from a manager who saw them through a tough quarter.
- Your position: Candidate B, because two years on her previous job suggest durability, and her side project shows she picks up new tools without being asked.
- What flips you: if Candidate A's reference says she shipped the hardest project of the past year, switch to A. If Candidate C's reference flags any communication problems, B stays.
That is the same Prediction Lock as Maya's. Different decision, different amount written under each part, same four parts.
Why four lines? Why not just one?
Each line catches a failure the others cannot, so compressing them into one line loses specific things.
- Skip Line 1, and you answer the wrong question. Maya's surface decision is "debate or coding." Her real decision is "follow my friends or pick on my own." Those have different answers. The label always hides the actual question, and Line 1 surfaces it.
- Skip Line 2, and your AI prompt collapses the lock. Without a specific question, you default to "which should I pick?", which invites AI to make the decision. Line 2 forces a closed, checkable question. "Does the bootcamp teach Python?" is checkable. "Which camp is better?" is not.
- Skip Line 3, and there is nothing to compare AI's answer against. This is the lock itself. It gives you a position to defend when AI's confident answer arrives.
- Skip Line 4, and you have a hope, not a commitment. "I pick debate" sounds like a decision. Until you name the AI answer that would flip it, you cannot tell whether you committed or will drop the position the moment AI suggests otherwise. Line 4 also lets you check, months later, whether your first guess was well calibrated, meaning close to what actually happened. That check is the only way judgment improves over time.
Maya's sticky now reads:
What's going on: Whether she'll do what her friends are doing or what she'd pick alone.
The question that would help: Will the bootcamp use Python (which her school already teaches in 9th grade)?
Decision: Debate. Two weeks with friends, learning something the school doesn't offer, beats a one-week repeat of next year's curriculum.
Confidence + what flips me: 70%. If the bootcamp teaches Rust, embedded systems, or anything her school doesn't cover, coding wins.
Now she types her question into ChatGPT. Here's the actual prompt she pastes:
My school's summer program runs a one-week coding bootcamp. I'm trying
to figure out one thing: will it teach Python? My school already teaches
Python in 9th grade, so I want to know if there's overlap. Just answer
the question. Don't recommend which camp I should pick.
The lock changed the question. Without the four lines, Maya would have asked "should I pick debate or coding?", an open question that hands the decision to AI. With the lock she already has a decision and needs one fact to confirm or overturn it, so she asks a closed question. AI's role shifts from decision-maker to fact-checker. That shift is what the discipline produces.
ChatGPT comes back with: "Most one-week coding bootcamps for middle schoolers cover Python basics in the first two to three days." Maya holds that next to her sticky note. AI's answer matches the answer she was prepared for. Her decision holds, for the reason she wrote down, not because AI told her so.
At dinner her dad asks why, and Maya has a real answer: "The bootcamp covers Python and my school's already teaching that next year. I'd rather spend two weeks with my friends learning debate, which the school doesn't offer at all." That is her reasoning. AI confirmed one fact inside it.
Compare that to the version without the lock. Maya asks "should I pick debate camp or a one-week coding bootcamp?" ChatGPT writes a balanced answer ending with "both are valuable, so consider what energizes you most." Maya picks debate because that is where her friends are going, and at dinner says "ChatGPT said both are good." The decision is the same. The reasoning is gone.
Those four lines are the Prediction Lock. Three minutes of writing, before AI's confident answer takes the spot in your head where your own answer would have gone.
Once you read AI's answer, you cannot un-read it. You cannot even tell what you would have thought without it. You just notice, two days later, that you cannot quite explain why you decided what you decided. You absorbed AI's answer. You did not earn your own.
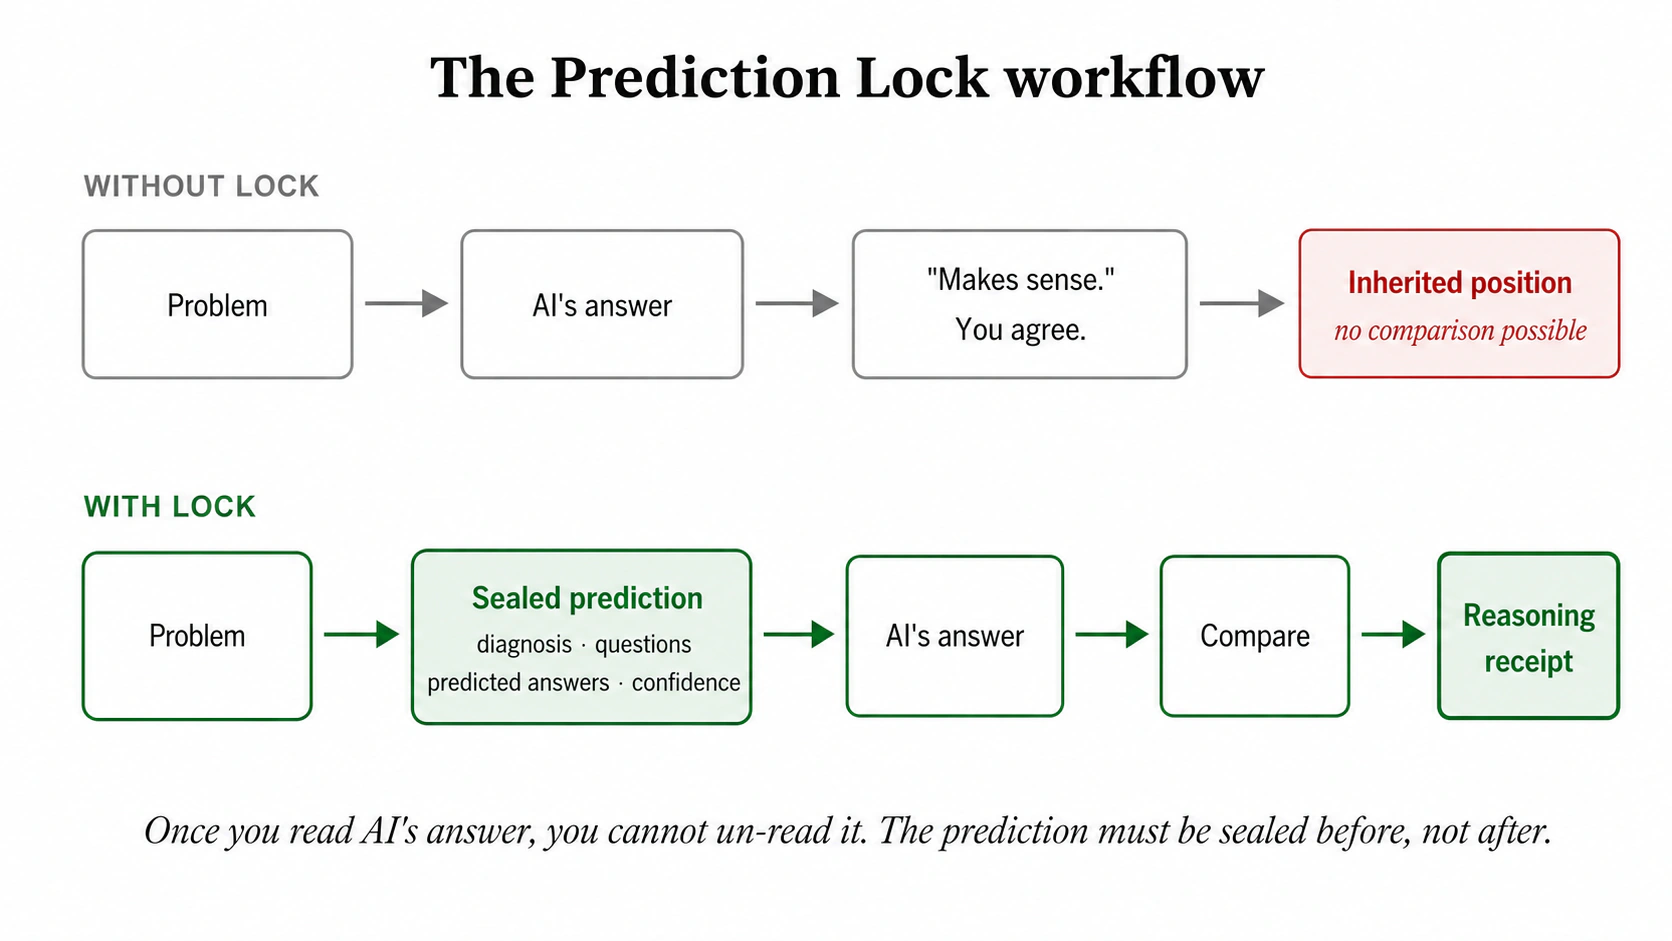 Sealed before the answer, or it isn't a prediction.
The same discipline works on bigger decisions. A bank manager had to decide whether to close two branches that were losing money. Before asking AI, she wrote her four lines:
Line 1 (what is this really about): The branches lose money because most customers now use the app instead of visiting in person. The real question is whether enough customers still walk in to justify keeping the branches open.
Line 2 (the one fact that would settle it): What percentage of these branches' customers are app-only (never visit the branch)?
Line 3 (my decision before AI weighs in): Close the branches. My experience working with the customer-service team suggests most of these customers stopped walking in years ago. I would not have predicted this two years ago, but the pattern has been clear since the app launched.
Line 4 (confidence + what flips me): 60% sure. If less than half the customers are app-only, that means a real walk-in base still exists, and closing the branches would lose those customers entirely. Keep the branches open in that case.
Then she pulled the transaction export and stripped it before it went anywhere. Names and account numbers came out. Each row became a branch-visit count and an app-login count. Line 2 asks for a percentage, and a percentage does not care which customer is which. Not every question is that lucky. When the identifiers are the substance of the question, removing them breaks the task instead of saving it. That fork belongs to Governance, Risk & Responsible Use. Hers was the lucky kind, so she pasted the anonymized rows and asked Claude:
I have transaction data for two branches we're considering closing.
For each customer who used these branches in the last 12 months,
I need to know what percentage NEVER walked into a branch and
only used the mobile app. Just give me the percentage. Don't
recommend whether to close the branches.
Claude came back with 45%. That is lower than her 50% threshold, which means her Line 4 flipped. Closing the branches was no longer the right call.
The more interesting thing was the gap. She expected most customers to be app-only. The data said 45%. That gap told her she had overestimated how far the customer base had moved. The data flipped her recommendation from "close" to "keep open," and the gap became her opening line: "I expected most of these customers to be app-only, and the data shows only 45% are, which changes the recommendation." She proposed a middle path. Keep the branches open with reduced staff hours, since 55% of customers were still walking in.
Without the Prediction Lock, she would have accepted whatever AI said and never noticed her own assumption was off. The middle path would not have surfaced either, because she would not have had a gap to notice.
Maya's four lines and the bank manager's four lines look different on the surface. They are the same Prediction Lock, the same four parts, applied to decisions of different sizes.
Now your turn
You already wrote four lines for Maya, and you can paste them into the boxes below. Or try the four lines on a decision of your own: something you want to buy, two plans you are choosing between, or a conversation you keep avoiding.
Write your four lines first. Then ask AI your Line 2 question using this prompt:
I'm trying to decide [describe your situation in 1-2 sentences].

My question is: [paste your Line 2 question here].

Just answer that one question. Don't make the decision for me.
Here's Maya's version of the same prompt, filled in from her sticky note:
I'm trying to decide between two summer camps. One is a one-week
coding bootcamp; the other is a two-week debate camp where all my
friends are going.

My question is: does the bootcamp teach Python? My school already
teaches Python in 9th grade, so I want to know if there's overlap.

Just answer that one question. Don't make the decision for me.
ChatGPT's response:
Most one-week coding bootcamps for middle schoolers cover Python
basics in the first two to three days, then move on to a small
project using those basics. Some bootcamps add light JavaScript or
web concepts later in the week, but Python is almost always the
core language.
Maya holds that next to her Line 4. Her Line 4 said coding wins only if the bootcamp teaches something her school doesn't cover. AI confirmed that Python is the core language, which is exactly what her school already teaches in 9th grade. That is not her flipping condition. Her decision stays: debate.
Only Lines 1 and 2 go into the prompt. Keep Line 3, your decision, and Line 4, what would change your mind, off the page AI sees. If AI knows what you have committed to, it tends to agree with you, and you lose the comparison the lock was built for.
Then compare AI's answer to your Line 4. You wrote down a specific finding that would change your mind. Did AI tell you that finding, or not?
-
If AI's answer is not what would flip you, your Line 3 decision holds, for the reason you wrote down. Maya: AI said Python, which her school already teaches, so her decision stays.
-
If AI's answer is exactly what would flip you, your decision changes, for the reason you set in advance, not because AI sounded confident. If AI had said "the bootcamp teaches embedded systems, not Python": that hits Maya's Line 4 exactly, so she switches to coding.
-
If AI's answer is somewhere in between, go back to your Line 3 reasoning. Does the new information weaken it? If yes, change your decision and write down why. If AI had said "Python for three days, then React": React is new to Maya, but two days of it does not beat two weeks of debate, so her decision stays.
If AI hedges instead of answering, ask again with one more sentence: "Just give me the specific information. Don't qualify it." If AI asks you a clarifying question, answer it and then add: "Now answer the original question." The goal is a concrete answer you can hold next to your Line 4, not a paragraph of "it depends on several factors." If your second attempt still fails, your Line 2 question is too broad. Make it more specific and try again.
A note on revising the lock. Sometimes AI's answer makes you realize you named the wrong flipping condition. That is a real signal, but be careful about when you revise. Revising Line 4 before you decide how to react to AI's answer is fine, because you spotted something you had missed and you are updating your thinking. Revising Line 4 after you have seen AI's answer, so that the answer does not count as a flip, defeats the lock. The test is whether you would have written the new Line 4 without seeing AI's answer. If yes, revise. If no, your old Line 4 stands.
Check that the lock worked. Try to finish the sentence "I decided this because..." out loud. If you can do it without using the words "AI said," the lock worked. If you cannot, find the line you skipped.
That sentence is the smallest piece of documented evidence of thinking you can produce. Not a polished answer AI handed you, but a reason you can point to. Every discipline below builds on it.
The exercise below does not check whether your decision is "right." It checks whether your four lines are clear. Did you name the real decision? Is your question specific? Is your position committed, rather than "it depends"? Did you name the AI answer that would flip you? It is okay if your first try is messy.
You have two options. Option 1: write four lines for Maya, using her decision and your own version of what each line should say. Option 2: write four lines for a real decision in your own week. The grader checks the same thing either way.
If you're going with Option 1, here are Maya's lines as a reference:
Line 1 (what's going on): Whether she'll do what her friends are doing or what she'd pick alone.
Line 2 (the question that would help): Will the bootcamp use Python (which her school already teaches in 9th grade)?
Line 3 (decision): Debate. Two weeks with friends, learning something the school doesn't offer, beats a one-week repeat of next year's curriculum.
Line 4 (confidence + what flips me): 70%. If the bootcamp teaches Rust, embedded systems, or anything her school doesn't cover, coding wins.
Fill in the four boxes and click submit. The grader scores each line and tells you what to improve, like a teacher checking your homework instantly.
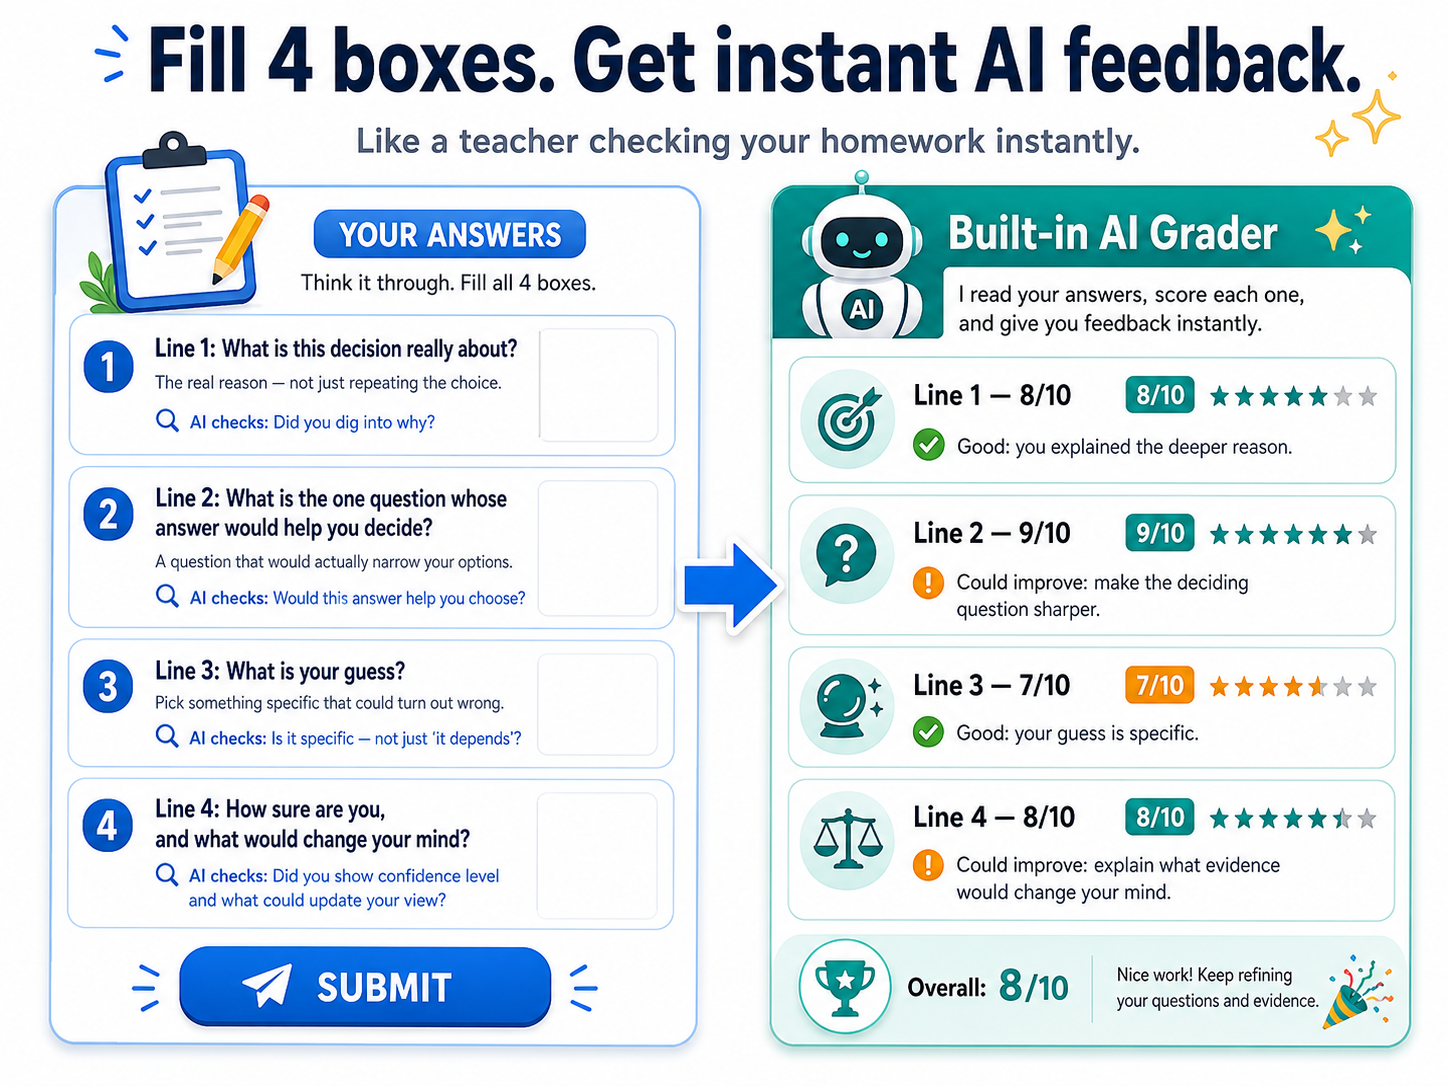
Discuss with an AI. Question your scores.
Come back when you have your BEST evaluation.
This takes about 8 minutes the first time. After you get your score, find one place where you think the AI grader is wrong. That is the most useful part of the exercise.
This covers half of Discipline 1. Keeping track of what AI says, and deciding what to do with each piece, is Discipline 2.
Details
Why this works (the research behind it)
The Prediction Lock is not a new idea. It is the AI-era version of three older techniques, each studied for decades.The premortem (Gary Klein, 2007). Before a project starts, the team imagines it has already failed and writes down all the reasons why. Writing the failure reasons first, before the optimism of the project takes hold, surfaces risks that would otherwise stay buried. Research by Deborah J. Mitchell, Jay Russo, and Nancy Pennington found that "prospective hindsight", meaning imagining that an event has already happened, increases the ability to correctly identify reasons for future outcomes by 30%. The Prediction Lock does the same thing on a smaller scale, and the writing-first part is what carries the weight.
Read Klein's original article: Performing a Project Premortem, Harvard Business Review, September 2007.
Forecasting calibration (Philip Tetlock, the Good Judgment Project, 2011-2015). Tetlock and his colleagues ran a multi-year tournament in which thousands of forecasters predicted world events. The best of them, whom Tetlock called "superforecasters", shared one habit. They recorded their predictions with confidence percentages before the answer arrived, then compared the prediction against the outcome afterward. Without the written prediction you cannot tell how close your guess was, because you rebuild your "prior beliefs" to match whatever happened. Line 4 is the smallest possible version of this practice.
Read about the project: The Good Judgment Project (Wikipedia). The book-length treatment is Tetlock and Gardner, Superforecasting: The Art and Science of Prediction (2015).
Anchoring (Amos Tversky and Daniel Kahneman, 1974). When a confident answer occupies the spot in your head where your own answer would have gone, it becomes your reference point, and you can no longer tell what you would have thought without it. Their original work used numbers. People asked to estimate a percentage after seeing an arbitrary number gave estimates pulled toward that number. Any confident answer that lands before you have formed your own becomes the anchor your later thinking adjusts from. AI's answers are confident by default, which makes them powerful anchors. The lock keeps the anchor from forming, because you place your own first.
The original paper is Judgment under Uncertainty: Heuristics and Biases, Science, Vol. 185, No. 4157, September 27, 1974, pp. 1124-1131. An open-access copy sits at this mirror.
All three at once. Write your decision and your flipping condition first, record your confidence so you can check calibration later, and do both before reading AI's answer. Four lines on a sticky note compress three decades of research into a three-minute habit.
Write your own position, and the one finding that would flip it, before you open AI. Then ask AI a closed question instead of "what should I do?" The four lines are only the method. The written position is the result.
Check yourself: What are the four lines of the Prediction Lock, and which two of them stay out of the prompt you send AI?
Discipline 2: The Reasoning Receipt
You spent the morning working with Claude on a report. The result looks good, so you send it off. Two weeks later someone asks: "Which parts of this did you actually check? Which parts did you change?" You have no answer. You read what AI wrote, it looked fine, so you used it.
This is the second-most common AI failure mode, after letting AI think for you. Even when you have your own position locked in, AI's drafts arrive in big polished blocks: five suggestions, a six-paragraph memo, a ten-row plan. You cannot defend any of it later, because you never tracked what you decided about each piece.
A Reasoning Receipt is a list of one-line notes, one note for each piece of AI output that goes into your final work. Each note says what you did with it and why. A shop receipt is written at the end, after the money is paid. This one is written while you work, and it changes what you decide. Not the whole thing at once. One note per piece.
Suppose you asked Claude to help you plan a group presentation, and it suggested: "Start the presentation with a short video clip to grab attention." You think about it. Your teacher said earlier this semester that visual openings get better grades, so the suggestion fits what you already know about this class. You decide to keep it.
That decision becomes one row in your receipt:
| What AI said | What you did | Why |
|---|---|---|
| Start with a short video clip to grab attention. | ACCEPT | Our teacher said visual openings get better grades. This fits. |
Three columns. What AI said (so future you remembers what was being decided), what you did (a one-word label), and why (one sentence so the row is defensible later).
Now suppose Claude's next suggestion was "Give each person 5 minutes to speak." You have four group members and 15 minutes total. The math doesn't work. So you reject it:
| What AI said | What you did | Why |
|---|---|---|
| Give each person 5 minutes to speak. | REJECT | We have 15 minutes for 4 people. The math doesn't work. |
That's the discipline. One row per AI suggestion, three columns each.
The five labels. What you did always falls into one of five categories. Most of the time you will use ACCEPT, REJECT, or MODIFY. The other two catch cases that are easy to skip.
| Label | What you did | Write one sentence explaining why |
|---|---|---|
| ACCEPT | You kept what AI said, no changes. | Why you trusted it. |
| REJECT | You decided AI was wrong and removed it. | What made you disagree. |
| MODIFY | You kept the idea but changed part of it. | What you changed and why. |
| SURFACED | AI brought up something you had not thought of. You kept it. | Why it matters. |
| MISSED | You noticed something AI forgot to mention. You added it. | What was missing and why it matters. |
ACCEPT, REJECT, and MODIFY are the basic moves. SURFACED marks the moments when AI taught you something, which is where it added thinking you would not have done alone. MISSED marks what AI did not say but should have, which is where your own judgment caught something the draft passed over.
A good receipt has a mix of all five over time. If every row says ACCEPT, you are not really thinking. You are signing off on what AI wrote.
"But nobody ever audits my work, so why bother?"
This is the most reasonable objection, and it deserves a real answer. Most readers, most of the time, will not be audited. Your boss does not ask. Your professor moves on. If the only payoff was "in case someone asks," the receipt would not be worth the trouble.
Keeping a receipt does three things even when nobody ever asks.
First, the act of writing changes what you decide. When you accept an AI suggestion silently, your brain processes it as "sounds right, moving on." When you have to write a label and a reason, your brain has to examine the suggestion. Most readers, on their first try, find at least one row where they cannot finish the "why" sentence. That row was something they were about to use without thinking. The receipt catches it before it goes out.
Second, the receipt becomes part of your work, not just a record of it. The bank manager turned the gap between her position and the data into the opening line of her report. A row labeled REJECT often becomes a "considered alternatives" paragraph in the final document. A row labeled SURFACED often becomes the most interesting thing you bring to the meeting.
Third, future you is the one who usually checks. Three months from now, you will look at this work and not remember which parts were yours, which were AI's, or why you decided what you decided. The receipt is a note to future you. Most of the times a receipt pays off, the question comes from yourself, not from a boss.
The audit is the most visible payoff, and the rarest. The other three happen every time, even when no one ever reads the receipt. The receipt is not separate from your work. It shapes the work as you produce it, and it is what you still have when your memory of the project has faded.
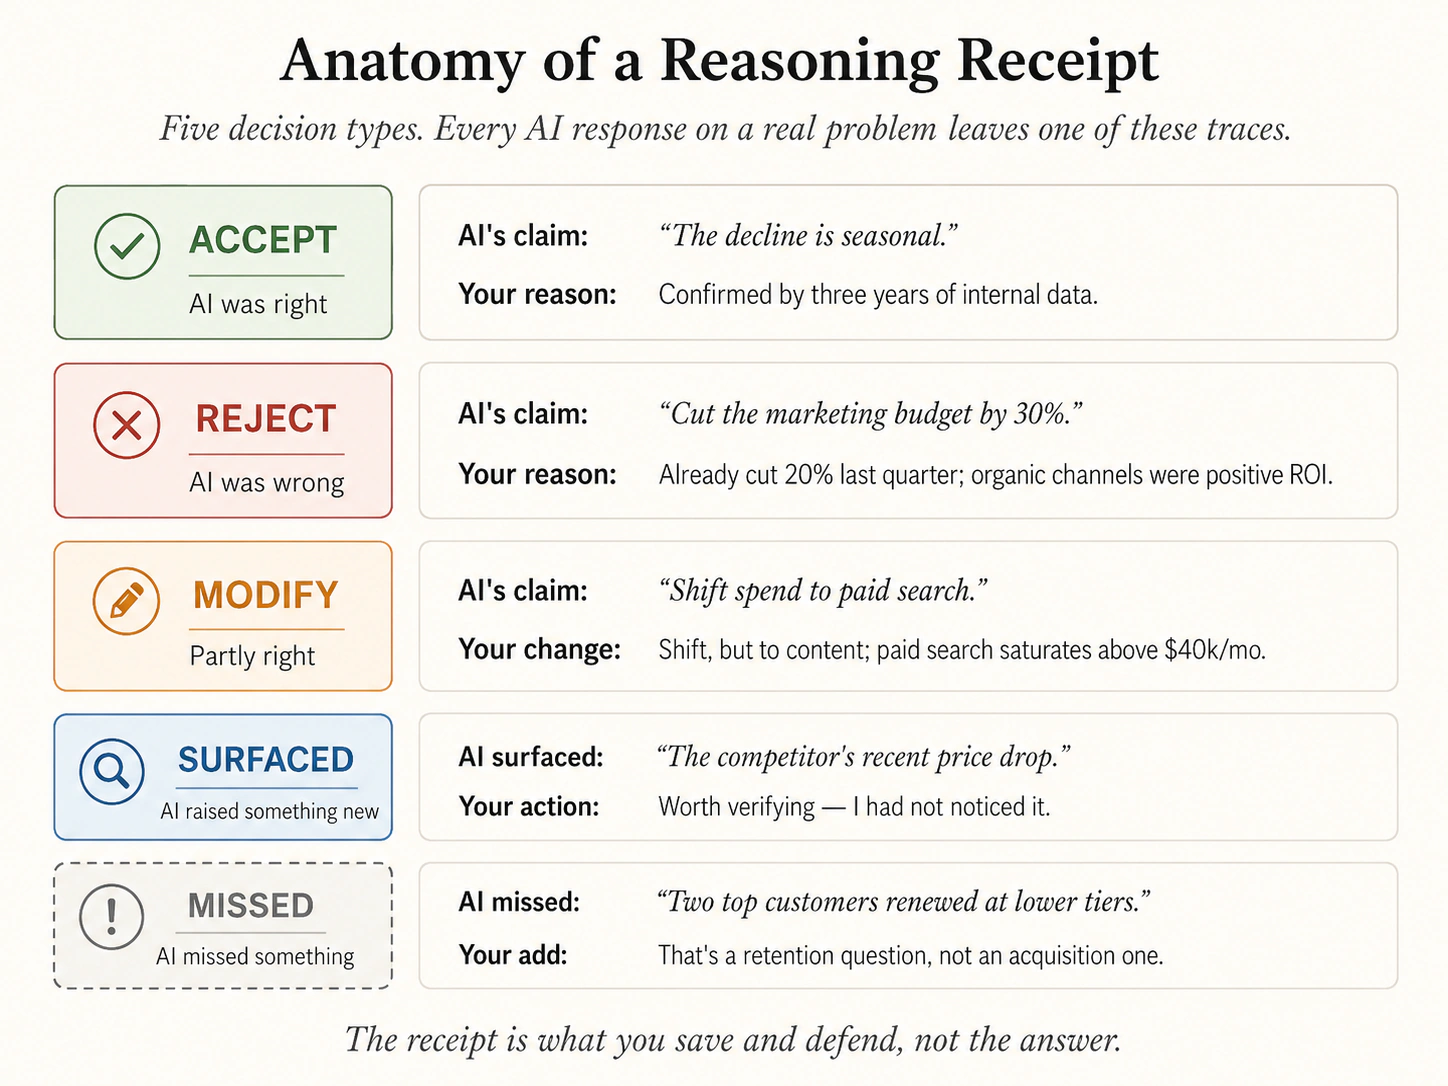 A receipt is one decision per row. The label tells you what you did. The "why" tells future you, or anyone else reading, why the row can be trusted.
A student asked Claude to help plan a group presentation for class. Claude gave a full plan. Instead of just using it, the student went through each suggestion and wrote down what she thought:
| What AI said | Label | Why |
|---|---|---|
| "Start the presentation with a short video clip to grab attention." | ACCEPT | Good idea. Our teacher said visual openings get better grades. |
| "Give each person 5 minutes to speak." | REJECT | We only have 15 minutes total and there are 4 of us. The math does not work. |
| "End with a Q&A session." | MODIFY | Q&A yes, but we will prepare 3 backup questions in case nobody asks anything. |
| "Add a live demo of the app you built." | SURFACED | I had not thought of this. A live demo would make our presentation stand out. |
| (AI did not mention who brings the laptop and adapter for the projector.) | MISSED | I added this. Last time our group forgot the adapter and wasted 5 minutes. |
She shared the receipt with her group. After the presentation, the teacher asked why they did not give each person 5 minutes. She pointed at row 2: "We only had 15 minutes for 4 people. The math did not work." That one sentence was enough.
What happens without a receipt:
| What AI said | Label | Why |
|---|---|---|
| "Start with a short video clip." | ACCEPT | Sounds right. |
| "Give each person 5 minutes." | ACCEPT | Sounds right. |
| "End with a Q&A session." | ACCEPT | Sounds right. |
| "Add a live demo." | ACCEPT | Sounds right. |
| (Nothing written down.) |
If every row says ACCEPT with "sounds right" as the reason, you did not really think about it. You just copied what AI said. A good receipt has a mix of labels. If you cannot explain why you accepted something, you did not actually decide to keep it. You just went along with it.
Try it yourself
You are organizing your university's annual tech fest. Ten team members, 3 weeks to go, marketing not started, and another university just announced a similar event on the same weekend. You asked AI: "Should we move the event one week earlier, or keep the original date?" For each of its five suggestions, pick a label and write one sentence of why.
- "Move it earlier. Being first matters when two events compete for the same audience."
- "If you keep the original date, students will compare the two events and may pick the other one."
- "Your social media posts get the most engagement on Thursdays, so start marketing this Thursday."
- "Moving one week earlier means your team has only 2 weeks to prepare instead of 3."
- "Most students decide which events to attend based on what their friends are going to."
The AI grader will check two things:
- Did you explain your reasoning, or did you just write "sounds right"? Rate 1-10. Quote my weakest explanation.
- Did you use more than one label? If every row says ACCEPT, you did not really think about it. Rate 1-10.
Do not rewrite my work. If a box is empty or vague, just say so.
Claim 1: "Move it earlier. Being first matters."
Claim 2: "Students will compare the two events and may pick the other one."
Claim 3: "Start marketing this Thursday because that is when posts get the most engagement."
Claim 4: "Moving earlier means only 2 weeks to prepare instead of 3."
Claim 5: "Students decide based on what their friends are going to."
Discuss with an AI. Question your scores.
Come back when you have your BEST evaluation.
This takes about 10-15 minutes the first time. Then look for any row where you wrote "sounds right" without a real reason. That is the row where you accepted AI's thinking without doing your own. Go back and write a real explanation for it.
That checks each suggestion one at a time. It does not catch mistakes inside a suggestion, such as made-up facts, outdated information, or confidence about something wrong. That is Discipline 3.
Want to see a good example? (Open this after you submit your own.)
Another student did the same tech fest exercise. Not the only right answer, but a good one.
| Claim | Label | Why |
|---|---|---|
| 1 | REJECT | Being first does not matter here. Students pick events based on what sounds fun, not which was announced first. |
| 2 | MODIFY | Students might compare, but only if they hear about both. If we market better, the other event does not matter. |
| 3 | ACCEPT | Our Instagram data from last semester shows Thursday posts get 2x more likes. This checks out. |
| 4 | SURFACED | I had not thought about this. Losing a week of prep time is a real problem because we have not booked the venue yet. |
| 5 | ACCEPT | This is true. Last year we saw a big jump in sign-ups after we added a "bring your friend" option to the registration form. |
| 6 | MISSED | AI did not mention that our biggest sponsor needs 3 weeks notice. Moving earlier means we might lose the sponsorship. |
Why this is good: Only two ACCEPTs, and both rest on real data, not on "sounds right". The MISSED row catches something AI could not know, the sponsor's 3-week notice rule.
What this does not try to do: be clever. Most rows are one sentence. The point is writing real reasons, not long ones.
Details
Why this works (the research behind it)
Writing down what you decided and why is one of the most studied habits in how experts think. Three bodies of work explain why it works.Reflection-in-action (Donald Schön, 1983). Schön studied how doctors, architects, engineers, and teachers actually work. Skilled professionals do not just act and move on. They keep a running internal commentary, noticing surprises and deciding what to do about them as the work unfolds, not in a review afterward. The ones who improved fastest made that commentary explicit instead of leaving it unsaid. The receipt is that commentary written down, while you are still in the work, where it can change what you do next.
Read more: Reflective practice (Wikipedia), which summarizes Schön's The Reflective Practitioner (Basic Books, 1983).
Single-loop and double-loop learning (Chris Argyris, 1977). Single-loop learning fixes the immediate mistake, so the answer was wrong and you change the answer. Double-loop learning steps back and asks whether the whole approach was wrong in the first place. Argyris found that smart, capable people get stuck in single-loop mode by default. They tune the output and never question the frame. A receipt where every row says ACCEPT is single-loop thinking made visible. Forcing a real "why" on each row, and noticing when you cannot write one, is what pushes you into the double loop.
Read Argyris's original article: Double Loop Learning in Organizations, Harvard Business Review, September 1977.
Elaboration and the generation effect (Brown, Roediger & McDaniel, 2014). Decades of memory research point to one finding. You remember something far better when you put it into your own words than when you re-read it. The act of generating the explanation, even a single sentence, is what builds the durable memory. Three months later, the row you wrote a real reason for is the one you will still understand. The row you rubber-stamped with "sounds right" will be a blank.
A summary of the central findings sits at Make It Stick: The Science of Successful Learning. The book is published by Belknap Press of Harvard University Press, 2014.
All three at once. You decide while still in the work (Schön), the forced "why" moves you from rubber-stamping to questioning the approach (Argyris), and your own words are what make it stick (Brown, Roediger & McDaniel). Nobody has tested the Reasoning Receipt against AI specifically, but the habit underneath it is well established.
Every AI claim that reaches your final work gets one row: what AI said, what you did with it, and why in one sentence. A receipt of nothing but ACCEPT is a receipt that did no thinking.
Check yourself: What are the five labels, and which one covers something AI never mentioned?
Part 2: Detection (catching what AI misses)
Part 1 taught you how to think before using AI. Part 2 teaches you how to spot mistakes in what AI gives back.
Here is the problem. AI sounds equally confident whether it is right or wrong, and its worst mistakes hide in the sentences that sound most polished. It also focuses on the one thing you asked about and ignores the side effects.
Discipline 3, the Error Taxonomy, is a checklist of six common AI mistakes, so you can scan for them by name before you trust the output. Discipline 4, Thinking in Systems, means refusing to stop at the first effect of a decision. You keep asking "if I do this, what else changes?", so you catch the side effects AI missed.
Discipline 3: The Error Taxonomy
This discipline is the practical answer to What AI Actually Is, Idea 3: the machine has no built-in truth-checker, so you are it. The six error types below are what 'being the checker' looks like in practice.
You have probably experienced this. You ask AI a question, the answer comes back smooth and professional, everything seems fine, and you use it. Three days later you find out one of the numbers was wrong, or a source does not exist. The mistake was sitting right there, but the writing sounded so good that you missed it.
The person who pays for a missed mistake is usually you, not some checker who catches you later. If AI told you a used car had 32,000 miles when it really had 58,000, you do not get embarrassed in a meeting. You buy the wrong car. If AI invented a statistic for your report, you made a decision based on a number that was never real. AI's mistakes hurt the person who acts on them first.
Why "taxonomy"? A taxonomy is a naming system, a fixed set of labeled categories, the way biologists sort living things into species. One difference: a living thing belongs to one species, but a single AI sentence can belong to two error types at once. The power is in the naming. "Check whether this is any good" is too vague to act on, and your eyes slide over the page. But "check whether there is a fabricated source" is a specific hunt with a specific target, so you stop at every citation and look. Naming the six categories turns a vague worry into six concrete searches you can run.
Here is how to catch them. Instead of reading AI's output and asking yourself "does this feel right?", go through it looking for one specific type of mistake at a time. There are six types:
| Mistake type | What it looks like | Where to look first |
|---|---|---|
| Factual error | A wrong fact: a wrong number, wrong date, wrong name. | Any sentence with a specific number. Exact-looking numbers make things sound researched. Example: "73.6% of people fail to check AI's numbers." I made that up. |
| Logical gap | The conclusion does not actually follow from the evidence. | Words like "therefore" or "so." Ask whether the evidence proves this, or whether a step is missing. |
| False confidence | AI states something uncertain as if it were a fact. | The smoothest paragraphs. "May" or "could" means AI knows it is unsure. A debatable claim with no hedge is the warning sign. |
| Missing context | AI left out an important detail that would change the answer. | Think what an expert would ask first. If you would ask "but what about X?", AI probably did not. |
| Fabricated source | AI mentions a book, article, study, or tool that does not actually exist. | Every source AI names. Search the title. If you cannot find it, AI probably invented it. |
| Stale fact | Something that used to be true but is not true anymore. | Anything that changes over time: prices, rules, laws, software versions, who runs a company. |
Take just the first type, Factual error. The instruction says to look at any sentence with a specific number. So you read AI's output and stop at every number, ignoring everything else. Suppose AI wrote "this car has 32,000 miles on the odometer." You do not ask "does this sound right?", because a wrong mileage sounds exactly as reasonable as a right one. You check it against the source. The photo of the dashboard says 58,000. Caught. You did not catch it by reading carefully. You caught it because you were hunting for one type of mistake, and a number is where you stopped.
That is the whole technique, repeated six times. You are not reading the output six times. You are reading it once with six questions in mind, stopping where each question points. The worked example next shows all six.
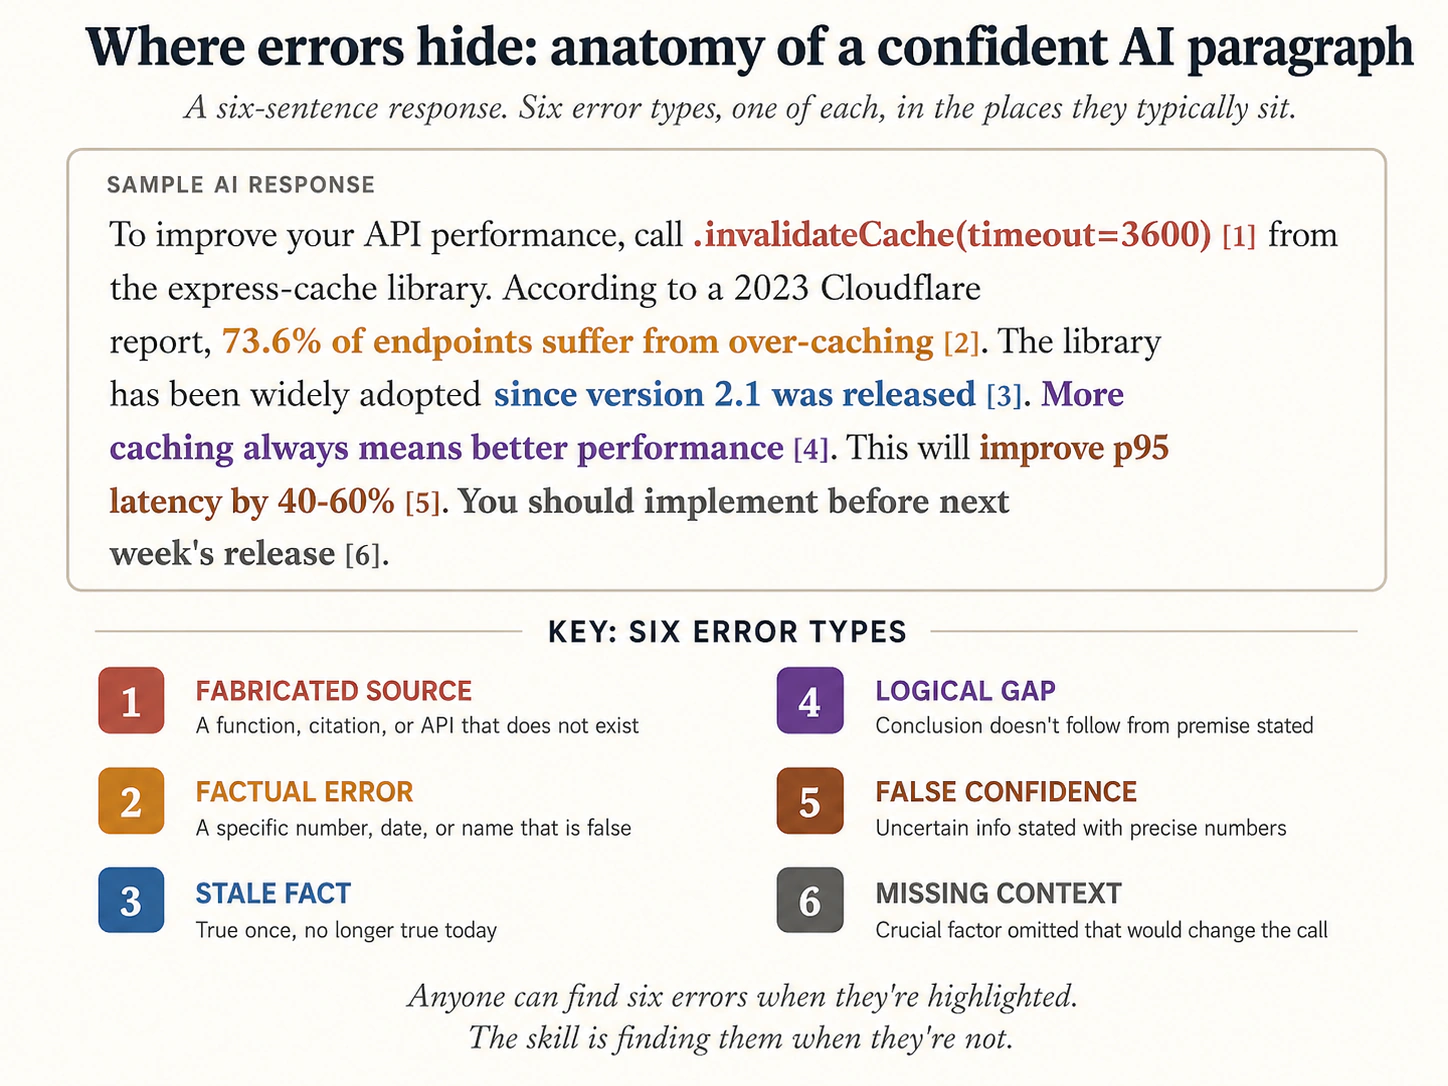 The six error types do not announce themselves. They hide inside the paragraphs that read as most professional, which is exactly why scanning by name beats reading by feel.
A parent was shopping for a reliable used car and found a 2021 Honda CR-V. Before driving an hour to see it, they asked Claude to look it over, pasting in the listing, the photos, and a note from their own mechanic. Claude wrote back a clean, confident summary: low miles, clean history, strong engine, a rebate to grab. They almost forwarded it with "let's buy this one." Instead, they ran the six-row scan.
| Error type | What they found in the write-up | Verdict |
|---|---|---|
| Factual error | Write-up said: "32,000 miles on the odometer." The listing photo of the dashboard clearly showed 58,000. Off by 26,000 miles. | Caught. Corrected from the photo. |
| Logical gap | Write-up said: "It has a clean accident history, therefore it has no mechanical problems." A clean accident record says nothing about the engine. The "therefore" did not hold. | Caught. A clean history is not a clean engine. |
| False confidence | Write-up said: "You will get at least 200,000 trouble-free miles out of this engine." No "should," no "likely," no basis. The flat promise was doing all the work. | Caught. Rewrote as "many CR-Vs last a long time, if serviced." |
| Missing context | Write-up never mentioned the timing belt, which is due for replacement around 60,000 miles. The parent's own mechanic had flagged it. The model never saw that note. | Caught. Added the belt as the first thing to check. |
| Fabricated source | Write-up said: "As Consumer Reports wrote in their March 2026 reliability issue, this is the most dependable small SUV on the market." The parent checked Consumer Reports. No such note. | Caught. Removed the quote. |
| Stale fact | Write-up said: "It still qualifies for the dealer's $1,000 loyalty rebate." The parent called the dealer. That rebate ended last month. | Caught. Dropped the rebate from the math. |
Five out of six mistake types showed up in one short summary. The hardest to catch was the fake Consumer Reports quote, because it sounded exactly like something a real magazine would write. Because the parent checked each mistake type by name, they went to see the car knowing the real mileage, the repair it needed, and the actual price. Notice who this protected. Not the parent's reputation with some checker, but the parent's own wallet. Trusting the summary would have cost them three ways. They would have driven an hour for a car they thought had 32,000 miles. They would have paid a price that counted on a rebate that no longer existed. And they would have skipped a repair they did not know was coming.
What happens if you just read without checking by type:
| How you read | What you miss | Why |
|---|---|---|
| You read the whole thing asking "does this sound good?" | Wrong numbers. Your eyes skip past numbers when everything sounds smooth. | Checking for "Factual Error" forces you to stop at every number. |
| You trust a quote because it names a brand you know | The fake Consumer Reports quote. Real magazine name, invented quote. | Checking for "Fabricated Source" forces you to look up every quote. |
| You read "therefore" as just a connecting word | The logical gap. "Clean history, therefore no problems" skips a step. | Checking for "Logical Gap" makes you stop at every "therefore" and ask what it proves. |
| You only notice missing info if something feels off | The timing belt replacement due at 60,000 miles. AI never mentioned it. | Missing information never jumps out. You have to ask what an expert would ask. |
The parent who checked by type and the parent who just read casually could be the same person. The only difference is how they read AI's output: one checked each mistake type by name, the other just read and hoped nothing was wrong.
The filled-in scan grid is worth keeping, not just running. It is documented evidence of thinking. When someone asks "did you check AI's numbers?", the grid is your answer. More often it is a note to future you. Six months from now, when you wonder whether you verified that statistic, the grid tells you.
Try it yourself
You are buying a used car this weekend, and the seller says another buyer is interested. You asked AI to compare two cars and tell you which to buy. Read what AI wrote back, then check it for each of the six mistake types. Start with Factual Error and Fabricated Source, because those two cost you the most money.
Which car should you buy?
Go with the 2020 Toyota Corolla. The Corolla gets 47 mpg combined, so you will spend far less at the pump than with most cars its size. According to the CarReliability Index 2026 rankings, the Corolla scores 9.4 out of 10, the top spot in its class. The 2019 Honda Civic is also a fine car. The Civic has lower mileage, therefore it is the more reliable choice if you want fewer surprises down the road.
Either car will run for another decade without a major repair, so you can pick on price and color and feel good about it. Both still qualify for the $2,000 state clean-vehicle rebate, which brings your real cost down nicely. Either way, you are getting a dependable car.
(If you prefer, you can skip the car example and use any real AI output from your own life instead: a homework answer, a college application draft, a research summary. The six mistake types work on any topic.)
The AI grader will check two things:
- Did you actually check each type, or did you just read and guess? Rate 1-10. A good answer has something written for every row. If you checked a type and found nothing wrong, write "checked, nothing found" instead of leaving it blank.
- Did you catch the important mistakes, or only the easy ones? Rate 1-10. If I missed a bigger mistake in the same write-up, tell me which sentence I should have caught.
Do not rewrite my work. If a row is blank without explanation, just say so.
For each of the six mistake types, copy the exact sentence from AI's write-up that has the mistake, and explain what is wrong. If you checked a type and found no mistake, write "checked, nothing found."
How sure are you about each one? (Rate 1-10 and say why in one sentence.)
Discuss with an AI. Question your scores.
Come back when you have your BEST evaluation.
This takes about 8-15 minutes the first time, and it gets faster. Then find one place where the AI grader disagrees with you. That disagreement is where you learn the most.
What you just did finds mistakes inside AI's answer. It does not catch what happens after you act on the advice. One decision causes another problem, which causes another. Discipline 4 teaches you to trace those chain reactions before they happen.
Want a strong sample to compare against? (Open after you submit your own.)
Another reader did the same used-car exercise. Not the only right answer, but a good one.
| Mistake type | Sentence from AI's write-up | What is wrong |
|---|---|---|
| Factual error | "The Corolla gets 47 mpg combined." | Wrong number. The real rating is about 33 mpg. This changes how much you would spend on gas. |
| Logical gap | "The Civic has lower mileage, therefore it is the more reliable choice." | Lower mileage helps, but it does not prove a car is reliable. The word "therefore" makes it sound proven when it is not. |
| False confidence | "Either car will run for another decade without a major repair." | Nobody can promise that about a used car. AI stated it as a fact with no "probably" or "likely." That is a guess pretending to be a fact. |
| Missing context | (Not in the write-up.) The 2019 Civic has an open airbag safety recall. | AI never mentioned this. A safety recall is exactly the kind of thing you need to know before buying, and AI left it out. |
| Fabricated source | "According to the CarReliability Index 2026 rankings, the Corolla scores 9.4 out of 10." | This index does not exist. AI invented a source that sounds real. If you search for "CarReliability Index," you will find nothing. |
| Stale fact | "Both still qualify for the $2,000 state clean-vehicle rebate." | That rebate ended in 2025. It was true once but is not true now. This would change the price you actually pay. |
Why this is good: Every row has an answer, and each quoted sentence would change which car you buy. The Missing Context row names a specific safety recall.
What this does not try to do: catch everything. Six rows in fifteen minutes is the goal, and three real catches beat thirty weak ones.
Details
Why this works (the research behind it)
When text is easy to read, we trust it more, whether or not it is true. AI writes very smoothly, which makes it a near-perfect trigger for that bias. Four findings explain why scanning by named type beats reading for feel.Processing fluency (Adam Alter & Daniel Oppenheimer, 2009). Reviewing decades of experiments, they showed that the ease with which we process something, such as clear type, simple words, and smooth phrasing, gets misread by the brain as a signal that the content is true. The feeling of "this reads well" leaks into the judgment "this is correct," even though the two have nothing to do with each other. Scanning for a specific error type breaks the spell. You stop judging how the text feels and start checking whether one kind of claim holds up.
Read the paper (open access): Uniting the Tribes of Fluency to Form a Metacognitive Nation, Personality and Social Psychology Review, 13(3), 2009.
Cognitive ease (Daniel Kahneman, 2011). When information arrives without effort, the fast, automatic part of the mind (System 1) accepts it and the slow, checking part (System 2) never wakes up. Smooth AI prose keeps System 2 asleep. Each named check is a task the automatic mind cannot do on autopilot, which forces the effortful look the fluent text was lulling you out of.
Read more: Thinking, Fast and Slow (Wikipedia). The relevant material is the chapter on cognitive ease.
Confidence is not accuracy (Nate Silver, 2012). Studying forecasters across politics, finance, and sports, Silver documented a consistent gap. The people who sound most certain are often the least accurate, because confidence and calibration are separate skills. AI states almost everything in the same assured tone, whether it is right or inventing. The False confidence row separates the tone from the truth. You flag the flat, unhedged claim as a warning sign.
Read more: The Signal and the Noise (Wikipedia).
Why six checks instead of one judgment. Gerd Gigerenzer's work on risk shows that how a problem is presented decides whether people reason about it well. Break a murky judgment into concrete pieces and accuracy jumps, even though the facts have not changed. "Is this AI output any good?" is exactly the murky, all-at-once judgment people are bad at. The scan breaks it into six questions you answer one at a time.
Read more: Gerd Gigerenzer (Wikipedia), summarizing the argument in Calculated Risks (2002).
All four at once. Fluent text feels true (Alter & Oppenheimer) and keeps the checking mind asleep (Kahneman), uniform confidence hides which claims are shaky (Silver), and a vague "does this seem right?" is the wrong way to present the problem (Gigerenzer). Naming six error types fixes all four.
The six-type scan works best when you know the topic. For topics you are new to, three tricks help:
- Ask AI for the exact source. Do not accept "studies show." Ask for the author, the title, the year, and where it was published. If AI cannot give you a real source, do not trust the claim.
- Be suspicious of exact-looking numbers with no source. "Sales went up 47.3%" sounds precise. If AI does not say where the number came from, the precision is a warning sign, not proof.
- When you are not sure, label it MODIFY. If you cannot check a claim in two minutes, do not ACCEPT it. Write MODIFY and add "not yet checked."
Do not ask whether AI's output feels right. Hunt it six times, once per named error type: factual error, logical gap, false confidence, missing context, fabricated source, stale fact. The person a missed error hurts first is you.
Check yourself: Which two error types cost you the most money in the used-car example, and what is the tell for each?
Discipline 4: Thinking in Systems
A university decided to save money by replacing some in-person tutoring with an AI chatbot. They asked AI, and AI said: "This saves 30% on tutoring costs." That sounded great, so they went ahead.
Six months later the students who struggled most had stopped coming for help, because the chatbot could not understand their questions. Their grades dropped. Parents complained. The university hired more tutors to fix the damage, and it cost more than the original budget. "Saves 30%" was correct on paper. The chain reaction wiped out the savings.
This is the failure mode of Discipline 4. AI answers the question you asked, such as "how much will this save?", and then stops. It almost never traces the chain reactions. Effect A causes Effect B, which causes Effect C, and sometimes Effect C circles back and undoes your decision. A Cascade Map is the drawing you make to trace those chains yourself, before you commit, so the surprise happens on paper instead of six months into a budget you cannot take back.
Nobody audited the university for a bad chatbot rollout. It spent the money, lived with the consequences, and spent more fixing it. The cascade map is not a defense you show later. It is the thinking that stops the expensive move.
Why "thinking in systems"? A system is any set of parts that affect each other. Students, tutors, budgets, and grades are not separate facts. They push on one another. Most of us reason in straight lines: this causes that, end of story. But the parts of a system are connected in circles, so an effect can travel around and come back to change the thing that started it. Thinking in systems means refusing to stop at the first effect. You keep asking "and then what?" until you find where the line bends back into a circle. The Cascade Map is the paper version of that habit.
Here is how to build one. It takes about 20 minutes the first time, and 10 once you are used to it.
- Write your decision in one clear sentence. Be specific. Not "maybe change tutoring" but "replace half of in-person tutoring hours with an AI chatbot starting next semester."
- List five groups of people this decision affects. Start with the people doing the work (tutors) and the people using the service (students). Add the people who compete with you (other universities). Then add the rules that apply to you (university policies), and what your team knows or does not know about the change (how good is the chatbot, really?).
- For each group, ask "and then what?" three times. Start with the first thing that happens. Then ask what that leads to. Then ask what comes after that. Three layers deep.
- Find where the effects come back. A loop is a chain where a later effect circles back and makes your original decision worse, or sometimes better. Find at least one, and be specific about how it happens.
- If your map looks clean and simple, you stopped too early. The real risks hide in the second and third layers. Push deeper until it looks messy.
Take the tutoring decision and one group, "students who struggle most." Start with the first thing that happens, then ask "and then what?" twice more.
- First layer: the struggling students try the chatbot. It cannot understand their half-formed questions, so they stop asking for help.
- And then what? (Second layer.) With no help, their grades drop. The students who most needed support got the least.
- And then what? (Third layer.) Some transfer to a university that still has human tutors, and the university loses their tuition.
That last link is where the surprise lives. The decision was "save 30% on tutoring." Three layers down it turns into "lose tuition from the students who needed us most." You only see that by asking "and then what?" three times in a row.
Now look for the loop. Lost tuition means a tighter budget, which means less money for tutoring, which means the chatbot covers even more, which means more struggling students give up. The original decision feeds itself. That is what turns a one-time 30% saving into an ongoing decline.
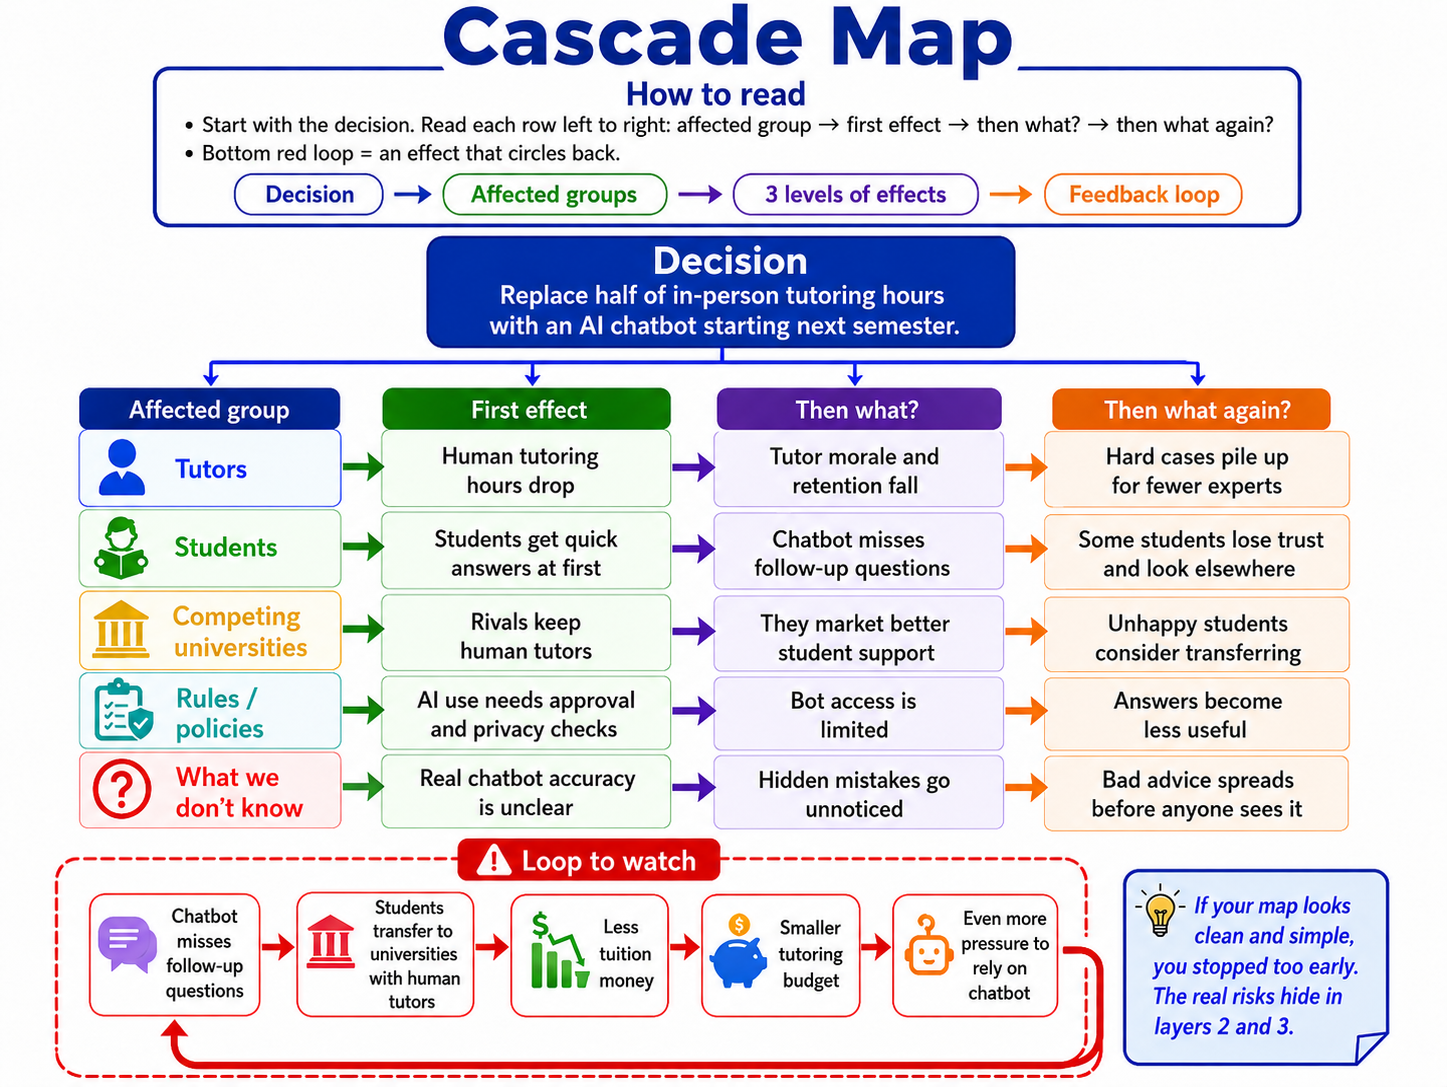
This drawing is the Cascade Map. The goal is not to predict the future perfectly. It is to find the loops before you commit, while changing the decision is still free.
If your map looks neat and tidy, you probably only wrote down the obvious effects. The real risks are in the deeper layers. Keep going.
You and AI have opposite blind spots here, which is why this discipline is a partnership. AI is good at answering the question you asked and bad at noticing the side effects your decision creates. You are better at thinking of the people AI forgot and the chain reactions that take months to play out. So you draw the map first, then ask AI to stress-test each branch you have drawn.
For a real decision, the map can take 20-30 minutes. The exercise below uses a shorter example so you can practice the technique.
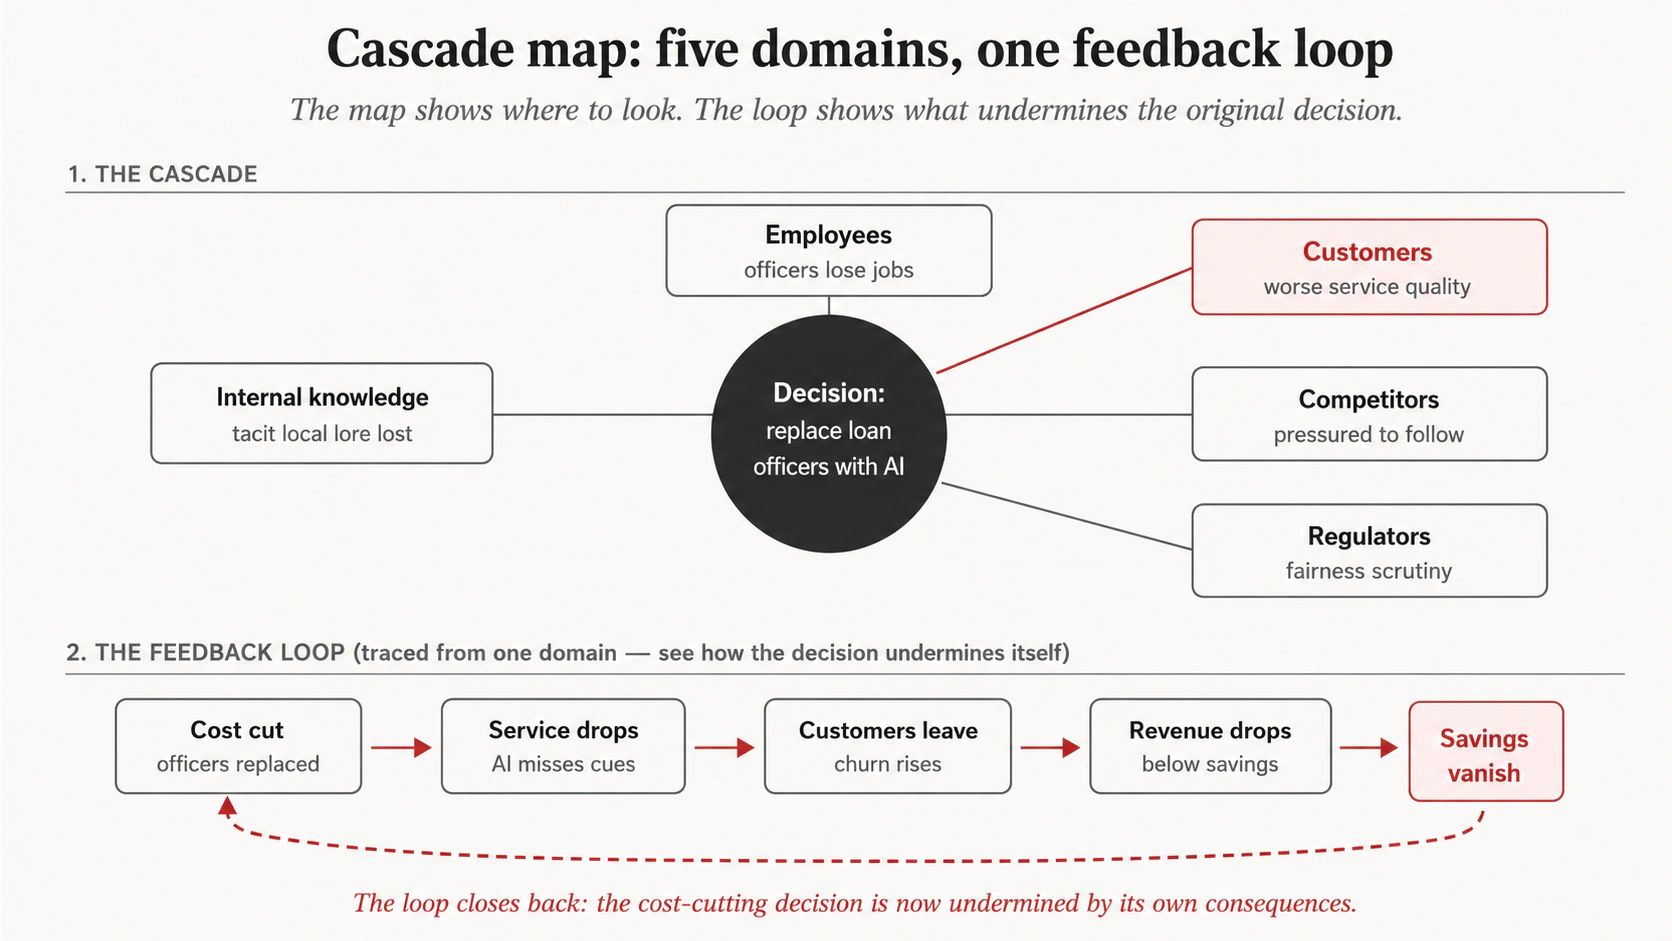 The map shows where to look. The loop shows what undermines the decision. The mess is the feature, not a bug.
Read the diagram in two passes. The top half is the breadth pass. One decision sits in the middle, "replace loan officers with AI," with five domains around it and the first thing that happens to each. Most are the effects anyone would list. Employees lose jobs, customers get worse service, competitors feel pressure to copy you. The one that is easy to miss is Internal knowledge: tacit local lore lost. Tacit local lore means what the staff know but never wrote down. Loan officers carry knowledge that never entered any system, such as which local businesses are reliable despite a thin credit file, or whose income is seasonal so a late payment in March is normal. Replace the officers and that knowledge walks out the door, because it was never in the software the AI learned from.
The bottom half is the depth pass, and it is why the decision backfires. Follow the Customers domain forward. The cost cut removes the officers, so service drops, because the AI misses the cues the humans used to catch. So customers leave, so revenue drops below what was saved, so the savings vanish. The dashed arrow is the whole point. The chain loops back to the start, so the cost-cutting move erases its own justification. That circling back is what you draw a cascade map to find.
Here is the same discipline on a different decision.
A student council president wanted to save money by moving the annual sports day from a rented stadium to the university's own ground. AI said "this saves 40% of the event budget" and listed the obvious benefits. No rental fee, closer to campus, easier to set up.
Before presenting the idea, she drew a cascade map. Her decision: move sports day from the rented stadium to the university ground to save 40% of the budget. She listed five groups and traced three layers for each. The first layers held no surprises. Saves money, less travel for students, smaller venue. The third layer revealed a problem she had not seen. The university ground holds far fewer spectators, so fewer families would attend, so the event would feel smaller, so sponsors who paid for visibility would pay less next year, so the budget would shrink, so the event would have to get smaller again. That is a loop, shrinking the event year after year without anyone deciding to.
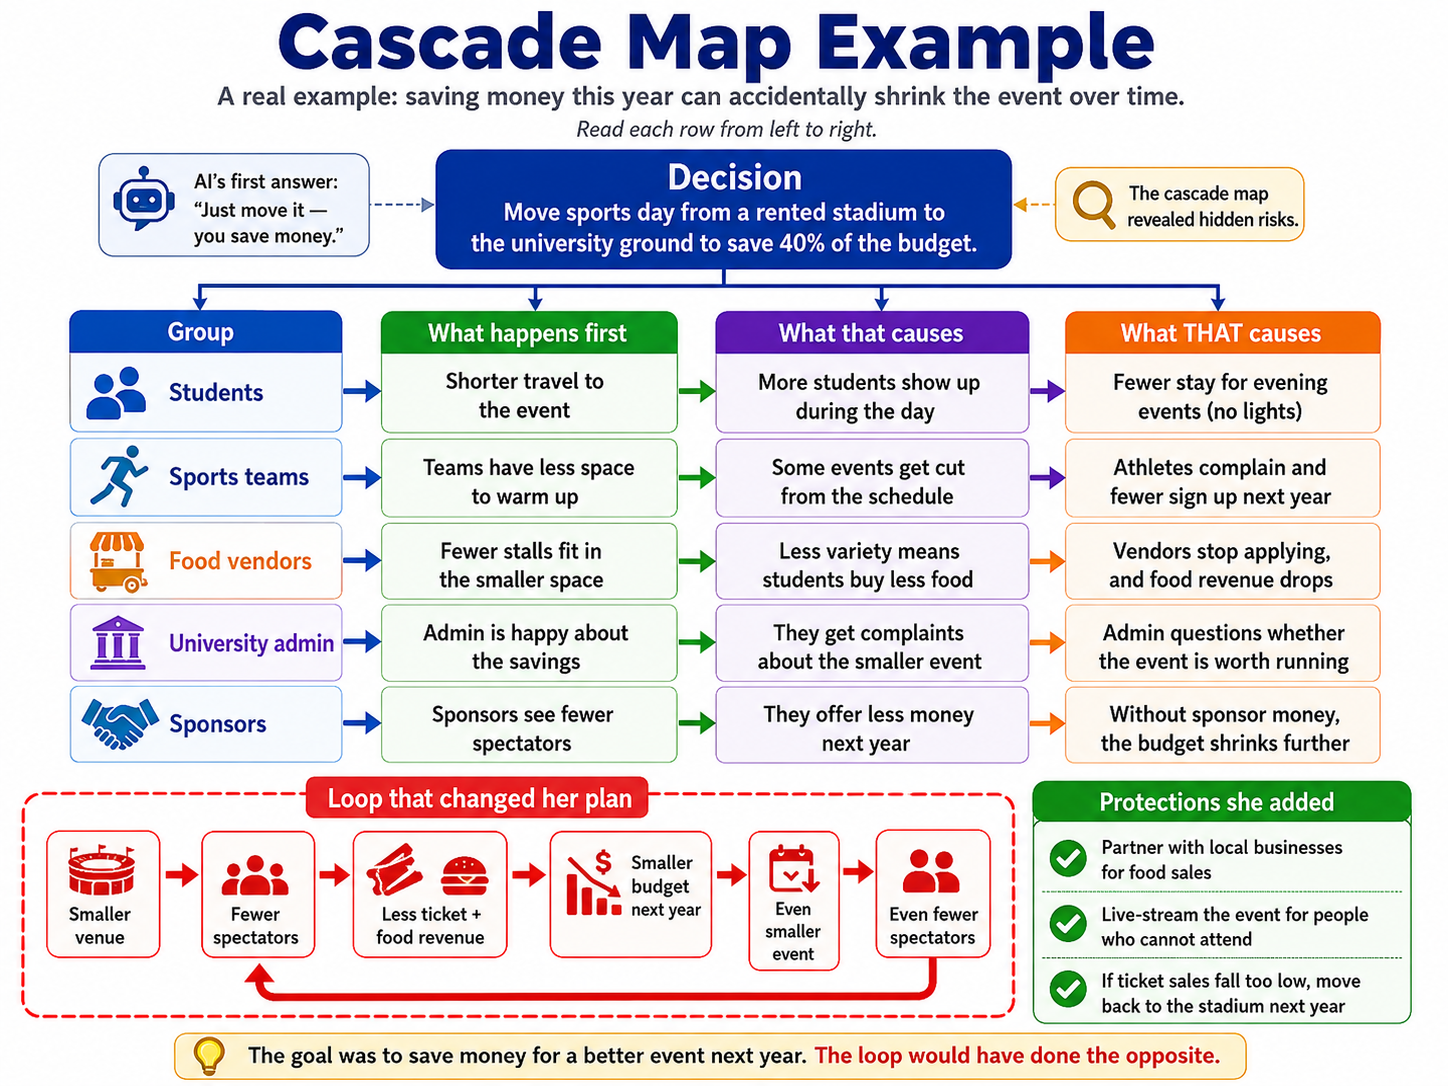
The image above shows her full cascade map. It covers what happens to each group (students, sports teams, food vendors, admin, sponsors), the loop, and the two protections she added against it. Those were a guaranteed minimum sponsor package and a spectator-capacity check before committing. AI's answer, "just move it, you save money," had neither. She still saved the money, without triggering the loop.
The map is itself a piece of documented evidence of thinking. When someone at the council asked "won't this shrink the event?", she did not have to think on her feet. She pointed at the loop she had already mapped and the protection she had already built.
Try it yourself
Your exercise. Your university just announced that all exams next semester will be online-only, with AI proctoring, meaning an AI watches you through your webcam. No more in-person exams.
Draw a cascade map with five groups: students, professors, IT staff, parents, and the administration. Go three layers deep for each group. Find one loop where a later effect circles back and makes the original decision worse.
(Or use any real decision from your own life this week. That is what makes it stick.)
The AI grader will check two things:
- Did you cover all five groups with three layers each, and did you explain how each effect happens (not just name it)? Rate 1-10. Tell me which group is the weakest and what I missed.
- Is your loop a real chain of cause and effect, or just a label? Rate 1-10. "Students react" is a label. "Students with bad internet fail exams, which lowers the university's pass rate, which makes administration rethink the policy" is a real chain. If mine is just a label, show me how to turn it into a chain.
Do not redraw my map. If a box is empty or vague, just say so.
Your cascade map (write the decision, then list each group with three layers of effects. It does not have to be neat):
Your loop (write it as one chain of cause and effect):
Discuss with an AI. Question your scores.
Come back when you have your BEST evaluation.
This takes about 15-20 minutes the first time. The first few "and then what?" questions feel awkward, and the real insights show up at the third layer, not the first. With practice a full map takes 8-12 minutes.
Then look for a group the AI grader mentioned that you forgot. That is your blind spot. If the AI found a loop you missed, pay extra attention to it, because loops are what tell you when a decision will backfire over time.
That traces what happens after a decision. It does not check whether the decision rests on the right information in the first place.
A perfectly mapped plan built on a wrong assumption still fails. It just fails later, with better notes. That is what Discipline 5 is for.
Want to see a good example? (Open this after you submit your own.)
Another student did the same AI-proctored exam exercise. Not the only right answer, but a good one.
Decision: All exams next semester will be AI-proctored and online-only.
| Group | What happens first | What that causes | What THAT causes |
|---|---|---|---|
| Students | Students with slow internet or old laptops struggle | Some get wrongly flagged for "cheating" by the AI proctor | Those students file appeals; trust in the exam system drops |
| Professors | Professors cannot see students during the exam | They cannot tell if a student is confused or stuck | Professors redesign exams to be shorter and simpler, which lowers the standard |
| IT staff | IT has to set up and support the proctoring software | Students call IT constantly during exam week with tech problems | IT is overwhelmed; response times get worse for everyone on campus |
| Parents | Parents worry about privacy (webcam recording) | Some parents contact the administration to complain | The university has to write new privacy policies, which takes months |
| Administration | Administration saves money on exam halls | But they spend money on proctoring software licenses | The cost savings turn out to be smaller than expected |
The loop: Students with bad internet get flagged for cheating → they file complaints → the administration has to hire people to review each complaint manually → this costs more than booking exam halls did → the administration considers going back to in-person exams → the original decision gets reversed.
Why this is good: All five groups, three layers each, and each effect explains how it happens. The loop is a real chain that starts with a student problem and ends by undoing the decision.
What this does not try to do: list every possible effect. There are more loops here, such as professors quitting and students transferring. The point is one real loop with a clear chain, not all of them on your first try. If your map looks tidier than this one, go one more "and then what?" deeper in your two weakest domains.
Details
Why this works (the research behind it)
The Cascade Map is a stripped-down version of system dynamics, a field that has spent seventy years documenting one stubborn fact. People reason in straight lines, but the world runs on loops. Three bodies of work explain why drawing the map beats thinking it through in your head.Demand amplification (Jay Forrester, 1958). Forrester, who founded system dynamics at MIT, showed that a decision made at one point in a chain ripples outward and comes back distorted. His most famous demonstration is now called the bullwhip effect. A small, steady change in customer demand at the retail end produces wild swings in factory orders upstream, because each link reacts to the link next to it without seeing the whole loop. The lesson goes far beyond supply chains. When you decide in straight-line terms, such as "this saves 30%," you miss the way the effect travels through the system and returns changed.
Read more at Bullwhip effect (Wikipedia), which traces the idea to Forrester's "Industrial Dynamics: A Major Breakthrough for Decision Makers," Harvard Business Review, 36(4), 1958.
Misperception of feedback (John Sterman, the Beer Game). Sterman ran a now-classic experiment in which players manage one link of a simple supply chain. Even MBA students and executives reliably create large, costly swings. They respond to what is in front of them and ignore the delays and feedback loops they cannot see. The failure is not a lack of effort or intelligence. The loops are invisible unless something forces you to lay them out, and the Cascade Map is that forcing, in five low-stakes minutes.
Read more: Beer distribution game (Wikipedia). The full treatment is in Sterman's Business Dynamics: Systems Thinking and Modeling for a Complex World (McGraw-Hill, 2000).
Where to intervene in a system (Donella Meadows, 2008). Meadows spent her career arguing that the most powerful places to change a system are almost never the obvious ones. The strongest place to push is usually a feedback loop, and those are the structures straight-line analysis never names. Her blunt point follows. You cannot adjust, weaken, or protect against a loop you have not drawn.
Read more: Meadows's essay on places to intervene in a system, which became the basis for her book Thinking in Systems (Chelsea Green, 2008).
All three at once. Decisions return distorted (Forrester), people miss the return trip unless forced to draw it (Sterman), and the loops they miss are the strongest places to act (Meadows). The AI-era twist is that you now have a partner with the opposite blind spot. AI is strong on the breadth you would forget and weak on the loops you are built to sense.
AI answers the question you asked and stops. Trace the decision three layers deep across five groups, then hunt for the loop where a later effect circles back and undoes it. A tidy map means you stopped too early.
Check yourself: What is a loop, and why is the third layer the one where the surprise usually lives?
Part 3: Origination (doing what AI cannot)
Part 1 taught you to think before asking AI. Part 2 taught you to spot mistakes in AI's answers. Part 3 is about something different: doing the thinking that AI cannot do for you.
AI has two big blind spots here. First, it gives you the most common answer, not the best answer for your situation. It gives you the average of what worked for a thousand other people, and your situation may be different. Second, AI gravity does not switch off just because you know its name. The longer you work with AI, the stronger the pull to stop thinking and simply accept. Disciplines 5 and 6 fix both problems, and they push back the hardest.
Before you start, learn one important phrase. A named threshold is a specific condition that tells you when a piece of advice stops working. "This advice works when your class has fewer than 30 students" is a named threshold. "This works sometimes" is not, because "sometimes" does not tell you when. You will use this phrase in a minute.
Discipline 5: First Principles
First principles thinking means working out what is actually true for your case instead of accepting an answer because everyone repeats it. Here is where you need it.
You are the president of your university's coding club. Every other club on campus just started charging membership fees. Your vice president, your club advisor, and two senior members all say the same thing: "We should charge fees too, everyone else is doing it." You ask AI. AI agrees. Everyone is pointing the same direction.
That agreement is the danger. When everyone lines up behind the same answer, including AI, it feels settled, and it is easy to stop thinking and go along. But the common answer is built on what works for most clubs. Yours might be the exception, and nobody in the room is checking whether it is. This discipline is how you check.
The check has a specific shape. You take the common advice and find the exact condition where it stops working. Most people who doubt advice produce a vague complaint, such as "charging fees is not always a good idea." That is useless, because "not always" never says when. The skill is turning it into a named threshold, a specific, numbered condition where the advice breaks.
Usually people picture first-principles thinking as building an answer from scratch. This discipline does the lighter, faster version. Instead of rebuilding the advice, you test it. You find the exact conditions where the common answer stops being true for you. Same root move, aimed at the boundary rather than at the blank page.
Watch the move once. Same situation, two ways of doubting the advice:
- Vague complaint: "Charging fees is not always a good idea."
- Named threshold: "When your club's main goal is to attract first-year students who have never coded before, and most of them cannot afford a fee, charging money will scare away exactly the people you are trying to reach."
The first one is a shrug. The second one tells you exactly when the advice fails, which is with first-years who cannot afford it, and why it fails, because the fee blocks the people the club exists to reach. The first changes nothing. The second changes your decision. That gap, between a shrug and a named condition, is the whole discipline.
Here is how to practice it. Pick a piece of common advice everyone around you, including AI, is telling you to follow. Write three rows, each describing a specific situation where that advice would not work. Use a real number or condition, not just "sometimes."
| The common advice | When does it stop working? (Use a specific number or condition.) |
|---|---|
If you cannot fill three rows with specific conditions, you have been following the advice without understanding it.
How to tell if your row is good: "When your club has more than 80% first-year members with no income, charging fees will cut membership in half" is useful, because it tells you exactly when the advice breaks. "Charging fees does not always work" is too vague to decide with.
Nobody was going to audit the club president for charging fees, because the whole room, plus AI, agreed. If she had followed the consensus, she would have made a worse decision, watched membership drop, and never known why. The threshold is not something you produce to defend yourself later. It catches a bad decision while everyone around you is still nodding along.
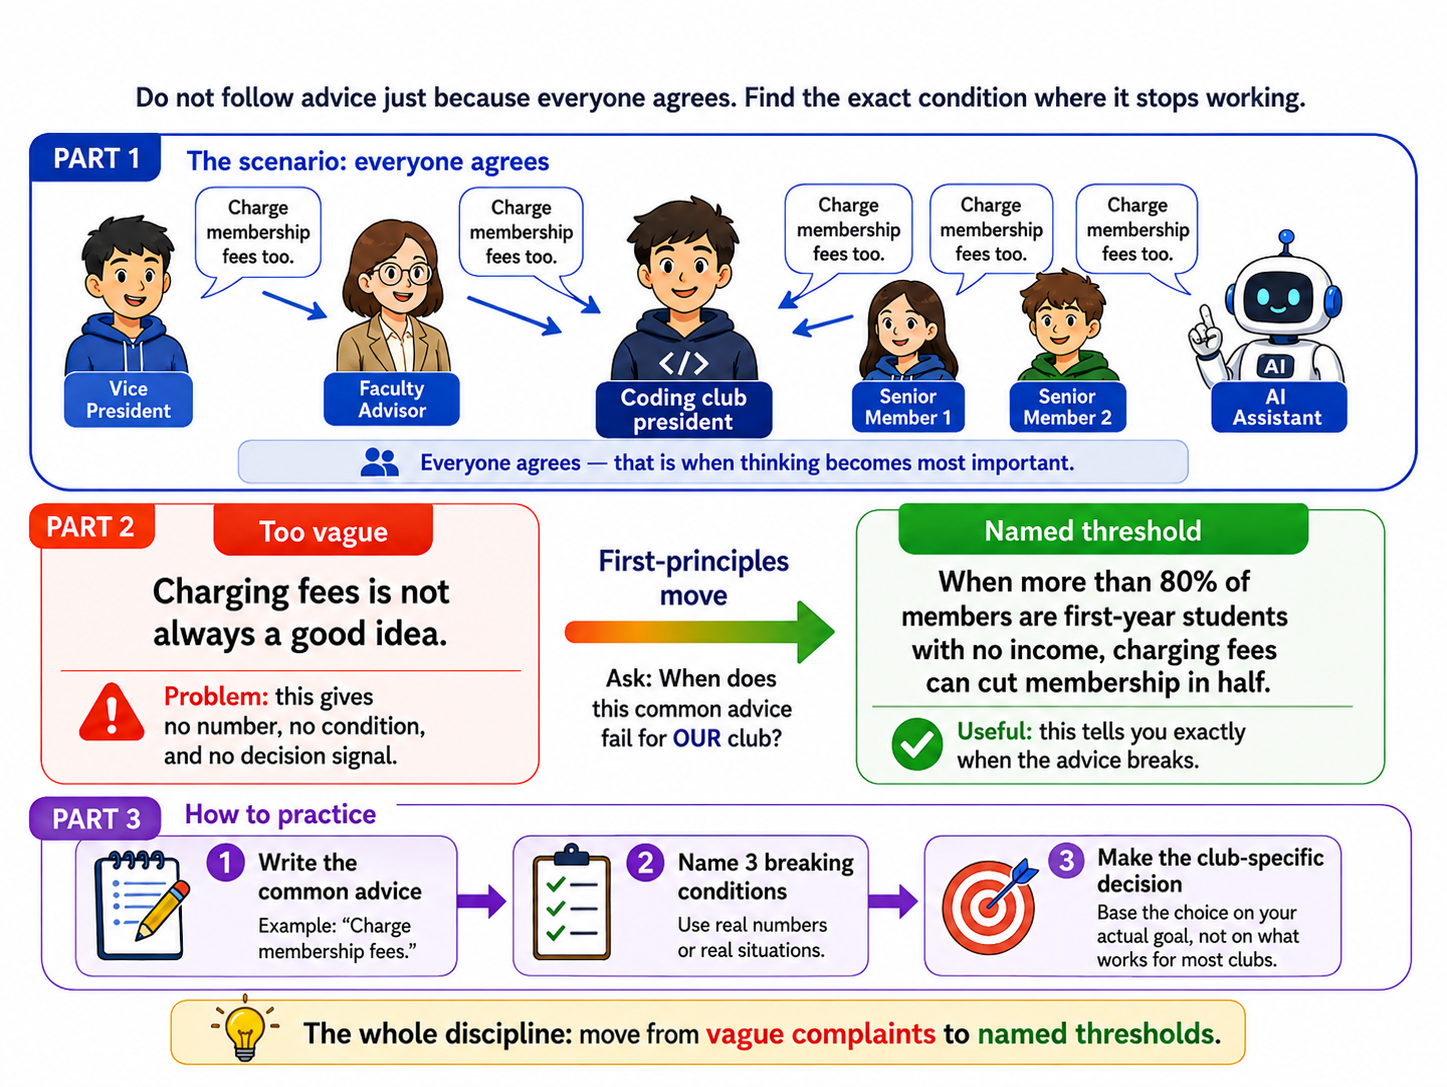
The coding club president above did not write three perfect rows on her first try. After thinking it through, she had this:
| Common advice: "Every club should charge membership fees." |
|---|
| Boundary 1. When more than 80% of your members are first-year students with no income, charging fees will scare away exactly the people you are trying to reach. Threshold: 80% first-year, no-income members. |
| Boundary 2. When your club's main value is free workshops that anyone can join, adding a fee creates a barrier that kills walk-in attendance. This matters most when your campus has 3 or more competing clubs that are still free. Threshold: 3+ free competing clubs on the same campus. |
| Boundary 3. When your club gets most of its budget from a university grant that requires you to be open to all students, charging fees could make you lose the grant. Threshold: a grant with an "open access" requirement that covers more than half your budget. |
She presented the three boundaries to her club advisor. They decided to keep the club free and raise money through sponsored hackathons instead. By the end of the semester, membership had grown 40%, while other clubs that started charging saw attendance drop. None of the three boundaries appeared in the common advice. None appeared in AI's first answer either.
Those three boundaries are also documented evidence of thinking. When the president sat down with her advisor, she did not say "I have a bad feeling about fees." She put three named conditions on the table. The difference between a feeling and three named thresholds is the difference between being overruled and being listened to.
Without named thresholds, she would have written something like this:
| Common advice: "Every club should charge fees." | Why this does not help |
|---|---|
| Sometimes charging fees is not a good idea. | Too vague. "Sometimes" does not say when. This could mean when 5% of members leave or when 90% leave. It does not help you decide. |
| Other clubs do not always know what they are doing. | This is a complaint about other clubs, not a reason for your decision. It does not change anything. |
| It depends on the situation. | Saying "it depends" without saying on what does not help. Everyone already knows it depends on the situation. |
Try it yourself
Your exercise. Pick any common advice people keep telling you, such as "follow your passion," "always study in a group," or "save 20% of every paycheck." Write three rows. In each row, name a specific situation, with a number or condition, where that advice stops working.
(This works the same no matter which advice you pick.)
Before you start. A threshold uses a specific number or condition. Words like "sometimes," "often," and "it depends" are not thresholds.
If you cannot come up with a third row, you have been following the advice without understanding it. Pick different advice instead of forcing a weak row. That itself is a useful discovery.
The AI grader will check two things:
- Does each row have a specific threshold (a number, a condition, a clear situation)? Rate 1-10. Quote the weakest row.
- Does each row explain why the advice fails in that situation, or does it just say "it does not work"? Rate 1-10. Point out any row that is a vague complaint instead of a real explanation.
Do not rewrite my rows. If a row is empty or vague, just say so.
The common advice I am examining:
Row 1: When does this advice stop working? (Name a specific condition and explain why.)
Row 2:
Row 3:
Discuss with an AI. Question your scores.
Come back when you have your BEST evaluation.
This takes about 15-25 minutes the first time. Thresholds are harder to write than you expect. Then look for any row where you wrote "sometimes" or "it depends" and rewrite it with a real number or condition. If you cannot, that row is not a real boundary. Drop it and try another.
That finds where one piece of advice stops working. It does not help you work with AI on problems with no obvious advice to challenge. That is Discipline 6.
Want to see a good example? (Open this after you submit your own.)
Another student picked the advice "always study in a group." Here are her three rows:
| Common advice: "Always study in a group." |
|---|
| Row 1. Groups bigger than 5 people do not work well. Most people just sit and listen while 2-3 people do the real work. When it breaks: more than 5 people. |
| Row 2. Some subjects need quiet focus, such as solving math problems or writing essays. In a group, someone interrupts you every few minutes. When it breaks: tasks that need more than 30 minutes of quiet thinking. |
| Row 3. When one person knows a lot more than everyone else, they spend the whole time explaining instead of studying. They fall behind on their own work. When it breaks: when the best and weakest student are more than 2 grade levels apart. |
Why this is good: Every row uses a specific number, and every row explains why the advice fails, not just that it fails. Three clear rows is enough.
Details
Why this works (the research behind it)
The First Principles move is to find the exact condition where common advice stops being true for you. It sits on top of three older ideas about why advice fails and how to test it.Ecological rationality (Gerd Gigerenzer, Peter Todd & the ABC Research Group, 1999). Their core finding fits in one short equation: heuristic + environment = outcome. A simple rule is never good or bad on its own. It is good in the environments it fits and bad in the ones it does not, and the whole skill is knowing which environment you are in. "Charge membership fees" is a rule tuned for clubs with members who can pay. Drop it into a club of first-years with no income and the same rule backfires. A named threshold states, precisely, the environment where the advice stops fitting.
Read more: Ecological rationality (Wikipedia), summarizing Gigerenzer, Todd & the ABC Research Group, Simple Heuristics That Make Us Smart (Oxford University Press, 1999).
Recognition-primed decisions (Gary Klein, 1998). Studying firefighters, nurses, and other experts under pressure, Klein found that they rarely weigh options. They recognize a situation as familiar and run the first pattern that fits, usually without noticing. That is fast and often right, but it is also how consensus advice slips past unexamined, because it feels like a settled answer. Writing down when the pattern would fail is the deliberate pause that interrupts the automatic match.
Read more: Recognition-primed decision (Wikipedia). The full account is in Klein's Sources of Power: How People Make Decisions (MIT Press, 1998).
Falsifiability (Karl Popper, 1959). Popper argued that a claim only tells you something about the world if you can state what would prove it wrong. A belief that survives every possible outcome explains nothing. A named threshold is that test applied to advice. "This works unless more than 80% of members cannot afford the fee" names the exact condition under which you would abandon it. "It doesn't always work" names no condition and so changes nothing.
Read more: Falsifiability (Wikipedia), the idea Popper introduced in The Logic of Scientific Discovery (1959).
All three at once. Advice is only right for the environment it fits (Gigerenzer & Todd), consensus slips past because recognizing a settled answer is automatic (Klein), and the cure is naming the condition that would prove it wrong for you (Popper).
When everyone agrees, including AI, that is the moment to check. Take the common advice and name the exact number or condition where it stops working for your case. "Not always" is a shrug. A named threshold changes your decision.
Check yourself: What turns a vague complaint into a named threshold, and why does the vague version change nothing?
Discipline 6: Working WITH AI
Working WITH AI means you do the thinking and the deciding while AI does the research and the drafting. Here is what happens when that split slips.
You spent the morning working with AI on an important essay. The arguments are clear and the writing is polished. Then your professor asks: "Which parts of this are your ideas and which parts came from AI?" You realize you cannot tell. Some sentences are yours, some are AI's, and most are a mix. The essay is good. You just do not know which parts you can defend.
Here is how to fix that. The three-path comparison means doing the same task three different ways and then comparing the results side by side.
- Solo. 15 minutes, no AI. Just you and the problem.
- AI-only. 5 minutes. Ask AI, accept the first answer, and change nothing.
- Collaborative. 10 minutes. Ask AI, read critically, disagree where needed, ask follow-up questions, and rewrite parts yourself.
Then compare all three. Which is best? Which parts of the collaborative version are better because of something you pushed back on? The collaborative version usually wins, but the real lesson is seeing exactly where your thinking made it better.
Suppose your task is the closing line of an email to a professor. Lay the three versions next to each other and read just that one line:
- Solo: "Thanks, and sorry again for the trouble." (Apologetic, a little weak.)
- AI-only: "Thank you for your time and consideration." (Polished, but it could be any email from anyone.)
- Collaborative: "I can show you what I have so far if that helps." (Yours, and it proves you have already started the work.)
Reading them side by side is the whole move. The Solo line shows what you would have written alone. The AI-only line shows what AI defaults to. The Collaborative line is the one you can defend, because it does a job neither of the others does. You do not just feel it is better. You can point at the line and say what it does. That pointing is the skill.
For a real project, the full comparison takes about 30 minutes. The exercise below is a quick 10-minute version so you can feel the difference today.
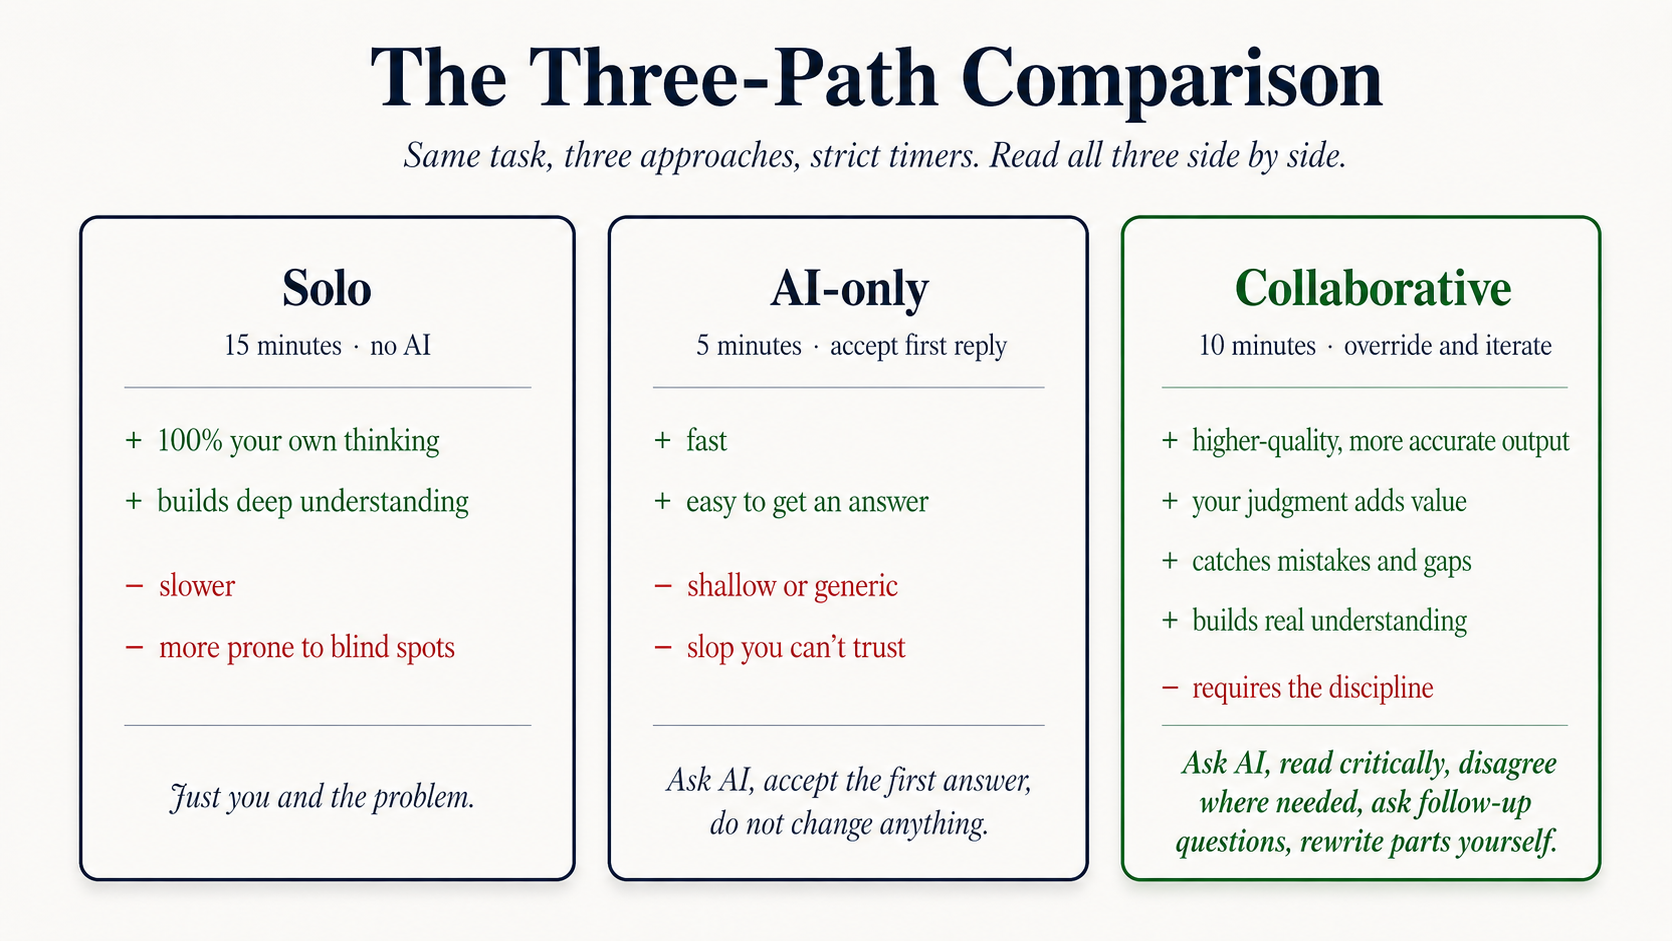
Here is what this looks like across a whole task.
A student had to write an email to her professor asking for a deadline extension on a major assignment. She had a real reason (she was dealing with a family emergency), but she needed the email to be honest without sounding like an excuse. She decided to try all three paths.
Solo, 15 minutes. She wrote the email herself with no AI help. It was honest and personal. She explained her situation clearly. But she rambled, and the actual request ("can I have 5 more days?") was buried at the bottom. The email was too long and the professor might not read to the end.
AI-only, 5 minutes. She gave AI the situation and accepted the first draft without changing anything. The email was polished and well-structured. But it sounded generic, like a template anyone could have sent. It did not mention any specific details about her situation. It did not sound like her. The professor would probably think she just copied an AI email.
Collaborative, 10 minutes. She wrote the opening herself, in her own words, then asked AI to restructure the email so the request came first. AI suggested softening the tone. She disagreed and kept her direct wording, because this professor prefers honesty over politeness. AI's closing line was too formal, so she rewrote it to match how she talks. The final email was clear, personal, and well-structured. The professor replied within an hour and gave her the extension.
The collaborative version won because of two specific things she did. She kept her own direct wording, which AI tried to soften, and she put the request at the top, which she would not have thought to do on her own. She can point to exactly where her judgment made the email better.
The three versions side by side are the documented evidence of thinking. The win is not "the email was good." Plenty of AI-only emails are good. The win is that she can show, line by line, where her judgment changed the result. That is what the professor's question, "which parts are yours?", was really asking for. The payoff did not depend on the professor asking. Even if no one had questioned it, the comparison made her email better than either other path would have produced.
Why you need all three versions, not just the Collaborative one:
- Without the Solo version, you cannot tell which ideas in the final email are yours and which came from AI.
- Without comparing all three, you cannot show that the Collaborative version is better. "It feels better" is not an answer.
- Without the AI-only version, you cannot tell if you just accepted everything AI said. If your Collaborative and AI-only versions look almost the same, you copied.
Use this where your personal experience matters: emails that need to sound like you, decisions where AI does not know your situation, creative work that needs your ideas. For simple tasks where AI does fine alone, such as formatting a table, just let AI do it.
Try it yourself
Start here. Write a message to your landlord asking for a rent reduction, or to your professor requesting a deadline extension. Something where you have context AI does not, such as your payment history or your relationship with the person.
Workplace version. Your boss asks for a one-page memo on whether your company should buy a smaller competitor. It has 90 people and was growing fast until last quarter, when it lost the customer who made up 22% of its revenue. They are open to being bought for $40-55M. Your recommendation will be quoted back to you for three years.
For either option, do all three versions: Solo (5 min), AI-only (3 min), Collaborative (5 min). The point is not the memo. It is the felt difference between the three paths.
(Or pick any real decision on your desk this week. The closer to something real, the sharper the comparison.)
Do not skip the AI-only draft. It is the most tempting to drop and the most revealing to keep. If your Collaborative version ends up close to your AI-only draft, you over-accepted, and you only learn that by writing both.
The AI grader will check two things:
- Are your three versions actually different, or do they all say the same thing? Rate 1-10. If the Solo and Collaborative versions look almost identical, say so.
- Are your three overrides specific? Rate 1-10. Each override should be something you can point to and say "without this, the email would have been worse." If any override is vague (like "I made it better"), say so.
Do not rewrite my work. If a box is empty or vague, just say so.
Describe each of your three versions (what you wrote, what surprised you, where it fell short):
Name three specific things you changed or added in the Collaborative version that made it better:
Which version would you actually send, and why?
Discuss with an AI. Question your scores.
Come back when you have your BEST evaluation.
This takes about 15 minutes including thinking time. Then look for a place where the AI grader says your Solo version was better at something. That is where your Collaborative version leaned too hard on AI.
What you just did is the whole crash course in one exercise. You formed your own opinion before asking AI, tracked what you agreed and disagreed with, checked for mistakes, thought about what happens next, tested where common advice stops working, and kept your judgment when AI tried to take over. The point was never the answer. The point is being able to show how you thought to get there.
Want to see a good example? (Open this after you submit your own.)
Another student wrote an email to her professor asking for a deadline extension. Here is what each version looked like:
| Version | What she wrote |
|---|---|
| Solo (15 min) | Honest and personal. Explained her family situation clearly. But it was too long, and the actual request ("can I have 5 more days?") was buried at the bottom. She knew it needed restructuring but ran out of time. |
| AI-only (5 min) | Short and well-organized. But it sounded like a template. It used phrases like "I would greatly appreciate your consideration" that she would never say in real life. It did not mention any specific details about her course or her professor. |
| Collaborative (10 min) | She wrote the opening in her own words, then asked AI to help her put the request at the top. AI suggested making the tone softer. She kept her direct wording, because she knows this professor likes honesty. She used AI's suggested structure but replaced the closing with her own sentence. |
Three things she changed in the Collaborative version:
- Kept her direct tone. AI tried to make it formal ("I would be grateful for your understanding"). She kept "I need 5 more days", because this professor prefers students who get to the point. Without it, the email would have sounded like every other AI-written extension request.
- Moved the request to the first line. AI suggested it, and she would not have thought of it. This was the biggest improvement over her Solo version.
- Replaced AI's closing line. AI wrote "Thank you for your time and consideration." She wrote "I can show you what I have so far if that helps," which shows she had already started the work.
Why this is good: Each override points to something she knew that AI did not. She can say exactly where her judgment made the email better. That is the test.
Details
Why this works (the research behind it)
This exercise is built on one pattern. Human plus AI beats either alone, but only when the human keeps the decisions. Three pieces of work explain it from three angles.Human plus machine teaming (Garry Kasparov, on "centaur" chess). After losing to IBM's Deep Blue in 1997, Kasparov helped popularize advanced chess, where a human plays alongside a computer. In the freestyle tournaments that followed, the strongest competitors were often not grandmasters and not the best engines. They were ordinary players skilled at managing the machine, knowing when to trust its calculation and when to override it. Today's engines are strong enough that a human rarely improves pure play, so the durable lesson is not about chess. Teaming wins when the human contributes something the machine lacks. In writing and decisions, that something is your private context, and the Collaborative path is what forces you to add it.
Read more: Advanced chess (Wikipedia). Kasparov develops the argument in Deep Thinking (PublicAffairs, 2017).
AI lifts the people who know least (Brynjolfsson, Li & Raymond, 2023). In the first large field study of generative AI at work, researchers tracked 5,179 customer-support agents given an AI assistant. Productivity rose 14% on average, but the gain sat almost entirely with beginners, at about 34%, with little effect on the most experienced agents. The AI was handing newer workers the knowledge the experts already had. The implication is direct. Collaboration adds value only when you bring something the AI does not already contain.
Read more: Generative AI at Work (NBER), published in the Quarterly Journal of Economics (2025).
AI compresses everyone toward the same middle (Noy & Zhang, 2023). In a controlled experiment, 444 professionals did writing tasks, half of them with ChatGPT. The tool cut time and raised average quality, but it did so by squeezing the range. Weaker writers improved a lot, stronger writers barely changed, and the outputs grew more similar. If you take AI's draft as it comes, you land on the same competent, generic middle everyone else lands on. Your overrides are what make the result yours.
Read the paper (open access): Experimental evidence on the productivity effects of generative artificial intelligence, Science, 381, 2023.
All three at once. Teaming beats solo work only when the human manages the machine (Kasparov), your value is whatever the AI does not already hold (Brynjolfsson, Li & Raymond), and unmanaged AI pulls every output toward the same middle (Noy & Zhang). The three drafts make all three visible at once.
Do the same task three ways: Solo, AI-only, and Collaborative. The Collaborative version only wins if you can point at the specific places where your judgment changed the result. If it looks like your AI-only draft, you over-accepted.
Check yourself: Why is the AI-only draft the one you must not skip?
A short recap before the capstone
You now have all six disciplines. One rule sits underneath them. The deliverable is never the answer. It is the documented evidence of thinking. The capstone below runs all six on a single decision.
The Capstone: One Decision, Six Disciplines
You are the president of your university's student council. The university just gave the council a surprise budget of $10,000 that must be spent before the semester ends. Option A is to hire an event planner for one big end-of-year farewell party. Option B is to buy AI tools that help every council member plan better events all year. Half the council wants each. You present your recommendation on Friday. Here is how each discipline helps.
Discipline 1, Prediction Lock. Before asking AI anything, you write your four lines. Real decision: not "farewell party or tools" but "one big event or making every future event better." Question that would settle it: will the AI tools actually get used by enough council members to justify the investment? Your position: pick Option B, the AI tools, because you have watched this council struggle with event planning all year, and the right tools would change the next four events, not just one. Confidence and what flips you: 55% sure. If fewer than 6 of the 8 council members would actually use the tools, switch to Option A.
Then you ask. Your Line 2 question was about the council members, so the answer comes from them, not from AI. You poll the eight directly. Six say they would use the tools and finish the training. That clears your bar of six, so your position holds, now with a number behind it instead of a hunch. Not every settling question is an AI question. The Prediction Lock tells you which question to answer, and sometimes you answer it by asking people.
Discipline 2, Reasoning Receipt. Now you ask AI for advice on how to spend the money. AI says the farewell party will "create lasting memories for 500+ students." You label it MODIFY, because the venue only holds 300. AI says AI tools increase event quality by 35%. You label it REJECT, because no source is given and your council has never used these tools. AI mentions that other universities saved money using AI for event planning. You label it SURFACED. You also notice AI never mentioned that a $10,000 party would need event insurance and security, so you label that MISSED and add it yourself. You end with 8 labeled rows, and you know which claims you trust.
Discipline 3, Error Taxonomy. The receipt handled the claims you stopped on. The error scan is for the ones you might have let through. You run AI's output past the six mistake types and catch three the receipt missed. A fabricated source: AI cited a "2025 National Student Events Report" you cannot find anywhere. A stale fact: the AI-tools price AI quoted is last year's, and the current price is about 15% higher. And false confidence: AI flatly claimed the tools "will pay for themselves in one semester" with nothing behind it. The stale price changes your budget math. The other two are reminders of how much of AI's confident tone was unearned.
Discipline 4, Cascade Map. You trace what happens with each option across five groups:
- Council members: Option A means one big event and then nothing. Option B means new skills for everyone.
- Students: Option A gives 300 students one great night. Option B improves every event for all students.
- University admin: Option A is safe and familiar. Option B shows the council is forward-thinking.
- Next year's council: Option A leaves nothing behind. Option B leaves tools and training the next team can use.
- Sponsors: Option A attracts sponsors who want visibility at one event. Option B is harder to pitch to sponsors.
You find one loop. If only 4 of the 8 members use the tools, the events do not improve, next year's council sees no benefit, and they cancel the tools. The investment is wasted. That is the reversal condition you named in Line 4, and it is real enough to build a safeguard against.
Discipline 5, First Principles. Everyone says "a big event builds school spirit." You test where that advice breaks. Boundary: when less than 20% of students can attend (300 out of 2,000), the farewell party builds spirit for a small group and the rest feel left out. That boundary changes the picture.
Discipline 6, Working WITH AI. You write your recommendation three ways. Solo gives a solid case for Option B, but you forgot to address the council members who want the farewell party. AI-only gives a polished recommendation that splits the difference, "do both", without explaining how to fit both in the budget. Collaborative is where you write the core argument yourself, ask AI to help you address the farewell party supporters' concerns, and add a specific rule. If fewer than 6 of 8 members complete the AI training within 3 months, the remaining money goes to the farewell party instead.
The council votes for Option B with your safeguard rule. You can explain every part of your recommendation, because you built it yourself, with AI's help.
What the six disciplines did. They did not give you the answer. They gave you the trail. A committed position with the finding that would flip it. A receipt showing which AI claims you trusted. An error scan that fixed your numbers. A cascade map that found the risk. A boundary that challenged the obvious choice. A comparison that produced the safeguard. Without them you walk into the meeting with "I think Option B is better." With them you walk in with evidence and a backup plan.
You do not need a Cascade Map to decide where to eat lunch. You do not need a Reasoning Receipt for every text message. Use the six disciplines for decisions that actually matter. For everything else, just decide and move on.
Which disciplines for which decision?
| How important is the decision? | Example | Which disciplines to use | Time |
|---|---|---|---|
| Not important at all | Choosing where to eat, replying to a routine message | None | 0-1 min |
| Somewhat important | Picking a course next semester, buying a laptop | Prediction Lock + Error Taxonomy on the top AI recommendation | 10-15 min |
| Important, with a deadline | Career choice, big purchase, group project proposal | Prediction Lock + Reasoning Receipt + Error Taxonomy + one or two others that fit | 30-60 min |
| Very important, people will judge your reasoning | Thesis defense, job interview presentation, council recommendation | All six disciplines | 90+ min |
🚀 Projects
The capstone above was someone else's decision. These four projects are yours. You do not ship a URL or build an app. You take a real decision from your own week, run it through the disciplines until you catch something you would have missed, and keep the trail.
The disciplines are built to catch. A premortem means imagining that your plan already failed and listing the reasons why, so it catches a way your plan fails. The receipt catches a claim you do not actually trust. The error scan catches a source AI made up. So the win here is small and real. It is a sentence you can say out loud. "I almost decided X, but I caught a way it fails, so I changed my plan." The thing you keep is a Decision Dossier, one short file, private to you, that answers "why did you decide this?" without you having to remember anything.
These are not exercises on a made-up case. The catch only counts if the decision is real and yours. The first project catches one way a plan fails. The second audits a confident answer. The third reframes the question itself. The fourth runs all six disciplines on one decision and keeps the result.
Project 1~15 minCall It Before It HappensLock your decision, then run a premortem to catch how it fails before you commit.
Pick one real decision you are about to make this week. Take the offer or stay. Buy the thing or wait. Have the conversation or let it go. Switch the plan or hold.
Write your Prediction Lock first, before you ask AI anything. Four short lines from Discipline 1: the real decision underneath the label, the one fact that would settle it, your position with its reason, and your confidence plus what would flip you.
Now run a premortem, the move the research box in Discipline 1 named. You imagine the decision already failed and ask why. Notice this is the one time you hand AI your decision on purpose. In Discipline 1 you kept your position off the page so AI would not just agree with you. Here you want it to attack, so you tell it exactly what you chose:
I've decided to [your decision]. Picture it's six months from now and this turned out to be a mistake. Don't reassure me. List the three most likely reasons it failed, most likely first, and keep them specific to my situation.
Read the three reasons against your Line 4. One is usually a failure mode you had not seen. That is the catch. Write one sentence of safeguard against it, the way the student council president added "if fewer than 6 of 8 members finish the training, the money goes to the party instead."
The win you can say out loud: "I caught a way this could fail before I committed, and built a safeguard."
Done when: you have named one failure mode the premortem surfaced that you had not seen, and written one line of safeguard against it. Keep both lines. They are the first page of your dossier.
Project 2~20 minAudit the Confident AnswerMake AI list its own claims, then catch the one it cannot actually back up.
Take a real question you would actually ask AI this week and let it give you a full, confident recommendation. Which laptop. Which loan. What to charge a client. How to handle the tenant.
Most readers find that recommendation polished and use it. You are going to audit it instead, with two disciplines at once. First the Reasoning Receipt: one row per claim, labeled ACCEPT, REJECT, MODIFY, SURFACED, or MISSED, with one sentence of why. Then the Error Taxonomy: scan the same answer for the six error types, especially a fabricated source, a stale number, and false confidence.
The fastest way to surface those is to make AI grade its own answer. Paste this right after its recommendation:
Go back through the recommendation you just gave me. List every factual claim as a numbered list. For each one, tell me plainly whether you actually know it or are estimating, and mark it KNOW or GUESS. For anything with a source, give me the exact title and year so I can look it up.
Now do the catching. Try to find one source it named. A real one survives a search. A fabricated one does not. Check one number against today's actual price or figure. The claim that does not hold up is your catch. Put it on your receipt with the reason and the error type.
The win you can say out loud: "It sounded sure, but I caught a made-up source, so I didn't just accept it."
Done when: you have one labeled row that is a real catch (a source you could not find, a number that was stale, or confidence with nothing behind it), and you can name which of the six error types it was. Add the receipt to your dossier.
Project 3~20 minThe Question That Unlocked ItStop asking AI for the answer. Work with it to find the question that makes the problem smaller.
This whole page argues that the power is in the question, not the answer. Here you prove it on something you are stuck on. Pick a real problem from your week, the kind you would normally dump on AI with "what should I do?"
First, write the question you would normally ask, in one line. Then do not ask it. Hand the problem over and ask for better questions instead of an answer:
I'm stuck on [your problem]. Don't solve it yet. Instead, ask me the five questions I should answer before I even try to solve this, ordered from the one most likely to change my whole approach down to the least. Then tell me which one I'm probably avoiding.
Read the list against the question you wrote first. Usually one of them, often the one it says you are avoiding, reframes the whole problem, because you were trying to solve the wrong thing. Answer that one question yourself, in a sentence or two, and watch the original problem change shape. That reframed question is your catch.
The win you can say out loud: "I stopped answering the wrong question, and the real one made the problem smaller."
Done when: you can name the reframed question that changed how you see the problem, and say in one sentence why the question you started with was the wrong one. Add both to your dossier.
Project 430-45 minThe Decision DossierRun one real decision through all six disciplines and keep the trail in one file.
This is the capstone. Pick one decision that actually matters this week, the kind where someone might ask you to justify it later: a hire, a big purchase, a project direction, a career move, a hard conversation. You will run all six disciplines on it and keep the result as your Decision Dossier. It is not a polished memo and it is not posted anywhere. It is the documented evidence of your thinking, in one place.
Open a blank doc. Each step below adds one short section.
- Prediction Lock (2 minutes). Write a 2-line lock: one sentence naming the real decision under the label, one sentence committing to a position with the specific finding that would flip it.
- Reasoning Receipt (5 minutes). Ask AI for its recommendation on your real question, then receipt three of its claims with ACCEPT, REJECT, or MODIFY and one sentence of why each. (The self-audit prompt from Project 2 makes the claims easy to see.)
- Error Taxonomy (3 minutes). Scan the AI output for one named error from the six types. Quote the exact sentence and name the type.
- Cascade Map (5 minutes). Pick three groups your decision affects. Write one layer of "and then what?" under each. Name one loop where an effect circles back on the decision.
- First Principles (3 minutes). Write one boundary row: the threshold where the advice everyone repeats stops working for your case.
- Three-Path Comparison (5 minutes). Write one short paragraph of your recommendation solo, then one with AI's help. Compare them. Keep the override: the line you wrote yourself that AI's version was missing.
It will not be polished. It will be yours, and it will be complete. A position you locked. The claims you trusted and the ones you did not. The error you caught. The risk the cascade found. The boundary you tested. The override you kept. That is the catch, scaled up to a whole decision.
The win you can say out loud: "Someone asked why I decided this, and I had the whole trail to show them, not just the answer."
Done when: you have one file with all six sections filled in for a real decision, and you could hand it to anyone who asks "why did you decide this?" and let it answer for you.
Where to go from here
For your next step in this book, pick a mode.
- If you write code, continue to Claude Code & OpenCode. The engineering surface for Mode 1 (using AI to improve work you already do).
- If you do knowledge work (legal, finance, marketing, operations, healthcare, education, leadership), continue to Cowork. The domain-expert surface for Mode 1.
- If you are ready to build AI Workers that run on their own, continue to Build AI Agents. This is Mode 2 (building AI systems that work independently).
The disciplines transfer across every tool, mode, and domain. They are what you carry from here to anywhere.
Glossary
If you got partway through the page and forgot what a word meant, here are the load-bearing terms in one place. The wording matches the Quick glossary near the top.
The four key ideas (from the rule section and the diagram).
- Discipline: a thinking habit you practice. Something you do.
- Failure mode: a specific way AI misleads you. Something AI does. Each discipline answers one failure mode.
- Part: a group of disciplines that share a job. This course has three parts, two disciplines each.
- Deliverable: what you hand to your boss, professor, or client. In 2026 it is the answer plus the documented evidence of thinking, which is the written record of how you reached the answer. If you cannot point at the evidence, you do not have a deliverable.
The six disciplines.
| # | Discipline | The action line | What it does |
|---|---|---|---|
| 1 | Prediction Lock (Part 1: Foundations) | PREDICT BEFORE YOU PROMPT | Write down your committed position before you ask AI, including the AI answer that would flip it. |
| 2 | Reasoning Receipt (Part 1: Foundations) | DOCUMENT EVERY DECISION | For each thing AI says, mark ACCEPT, REJECT, MODIFY, SURFACED or MISSED, with a one-sentence why. |
| 3 | Error Taxonomy (Part 2: Detection) | PREDICT WHERE ERRORS HIDE | Scan AI's output for six mistake types: factual error, logical gap, false confidence, missing context, fabricated source, stale fact. |
| 4 | Thinking in Systems (Part 2: Detection) | CASCADE MAPS & LOOPS | Trace what a decision causes across the groups it affects, three layers deep, and find the loops where effects circle back. |
| 5 | First Principles (Part 3: Origination) | FIND THE BOUNDARY | Name the named threshold, the specific number or condition where common advice stops working. |
| 6 | Working WITH AI (Part 3: Origination) | OVERRIDE & ITERATE | Compare what you write Solo, what AI writes alone, and what you write Collaboratively. The Collaborative version wins only if you can point to specific overrides where your judgment made it better. |
A few other terms used on the page.
- Named threshold: the exact number or condition where a piece of advice stops working. "This works when your class has fewer than 30 students" is one. "This works sometimes" is not.
- Cascade Map: the one-page drawing of what a decision causes, three layers deep, with a short column for each group your decision affects and three arrows under each.
- Reasoning Receipt: one row per AI claim, saying what you did with it and why. The labels are ACCEPT, REJECT, MODIFY, SURFACED, and MISSED.
- Loop: a chain where a later effect circles back and changes the original decision, usually making it worse.
Flashcards Study Aid
Test Your Understanding
The disciplines are not the deliverable. They are how you produce the evidence that is.
Does this make AI a more powerful tool in your hands, or does it make you a slower version of the tool?
Professor So's version of the same test: the tools you use are not the same as the skills you own. If your thinking stops when the machine is off, it was never your thinking.